



Gamer is miHoYo's new vision-language-action (VLA) foundation model that plays long 3D games from screen pixels and human-style keyboard and mouse commands — no hidden game-state API. The Honkai AI R&D team posted the arXiv paper on November 13, 2026, opened the project page, and shipped Apache-2.0 code that documents how a single policy reasons, remembers, and acts across hour-long quests.
For builders, Gamer is not a miHoYo storefront feature. It is a research stack — continued pre-training on tens of thousands of hours of gameplay, sparse-thinking supervision, Temporal-Aware GRPO (TA-GRPO) reinforcement learning, and Streaming-vLLM serving aimed at sub-100 ms decision loops. That combination is why the Hugging Face Daily Papers entry hit #2 with rising upvotes: it connects embodied agent roadmaps to something millions of players already understand — beating a hard RPG quest under time pressure.
TL;DR
| Question | Answer |
|---|---|
| Who released it? | miHoYo Honkai AI R&D Team (authors on arXiv and GitHub) |
| What interface? | Screen observations in, keyboard and mouse action tokens out |
| Training recipe? | CPT on massive trajectories → sparse-reasoning SFT → TA-GRPO online RL |
| Serving? | Streaming-vLLM with KV reuse and speculative decoding; README cites ~20× latency drop on H200/Qwen3.5-35B-A3B MoE |
| Code? | GitHub RainBowLuoCS/Gamer — prompts, parsers, benchmark tables; weights not bundled as a product drop |
| How does this compare to cheat headlines? | Unlike GPT-6 Astra's StarCraft shortcut, Gamer's setup forbids swapping in human bots mid-episode; rewards come from environment verification |
Why miHoYo built a game-native VLA now
Games are stress tests for agents: partial observability, long horizons, sparse rewards, and real-time control at 30–60 FPS. Productivity computer-use agents often click through forms. RPGs demand memory (“which door did I already try?”), combat sequencing, and navigation across maps that do not fit one context window.
miHoYo's angle in the abstract is generalist control: the same action vocabulary (mouse deltas, key holds, scroll) should work in 2D benchmarks and 3D open worlds, and trajectories can mix virtual games with embodied simulators so dynamics transfer. That mirrors how Microsoft's idle-GPU gaming patent and Xbox Labs' AI porting experiments treat commercial titles as data factories — except Gamer publishes the training and inference recipe, not just IP around it.
What games did miHoYo make? The studio is known for Genshin Impact, Honkai: Star Rail, Zenless Zone Zero, and related live-service titles. Gamer is not a new game in that list; it is an R&D agent evaluated partly inside Honkai: Star Rail quests, with demo art on the project page referencing multiple franchises for benchmark variety.
Architecture: perception, sparse reasoning, and memory
The policy is end-to-end: vision encoder + language backbone + action head that emits structured keyboard and mouse chunks. Three ideas separate it from a vanilla VLM fine-tune:
- Unified visual control — actions are device-level trajectories aligned to frames, not abstract joystick vectors tied to one title.
- Sparse reasoning — the model can output action-only tokens when the prior plan still works, and only opens a reasoning block when objectives change (documented in the GitHub system prompt template).
- Persistent memory summaries — when the context window fills, the agent writes compact memory of finished subgoals, failures, and remaining plan steps, then continues rolling forward.
Sparse reasoning and cross-context memory
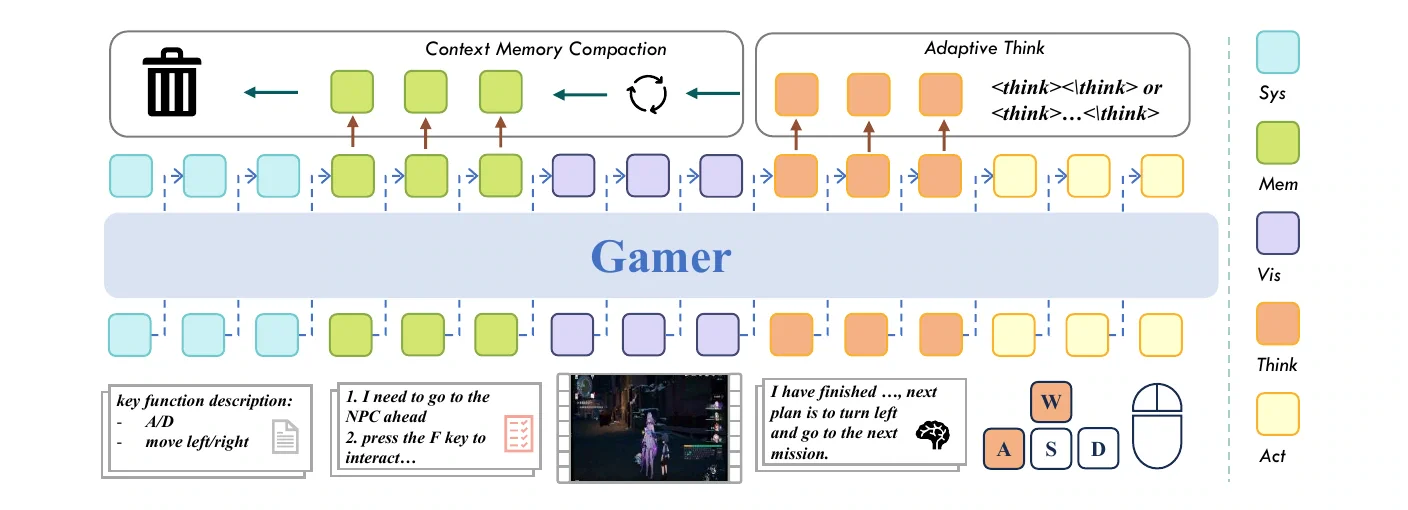 Gamer VLA model sparse reasoning and cross-context memory architecture diagram
Image: miHoYo Honkai AI R&D Team
The figure above (from the official project page) shows how reasoning and memory updates share the same autoregressive stream as low-level actions. That matters for deployment: you do not run a separate planner service that drifts from the executor.
Practically, each decision covers about 200 ms split into six ~33 ms steps. Mouse movement applies to the whole chunk; keys can differ per step. The README lists 74 case-sensitive key tokens and strict parsing rules — including treating malformed outputs as no-ops, which is how you keep an RL farm from melting down when the policy hallucinates format.
If you build agents, steal the pattern: one tokenizer for thought, memory, and act, with the harness enforcing FSM-shaped structure so speculative decoding can propose safe delimiters.
Training stages: CPT, SFT, and TA-GRPO
The GitHub method table breaks training into three supervised regimes plus online RL:
| Stage | Supervision | What the policy learns |
|---|---|---|
| Continued pre-training (CPT) | Screen frames paired with keyboard and mouse from diverse games plus general multimodal data | Transferable visual control and dynamics before task-specific rewards |
| Sparse-reasoning SFT | Multi-level instructions with ~1.2M reasoning and ~223K memory annotations (per Hugging Face team post) | When to think, what to remember, and how to finish subgoals |
| TA-GRPO | Online rollouts with verifiable environment outcomes | Long-horizon credit assignment across segments linked by memory |
Temporal-Aware GRPO is the paper's answer to context limits and rollout error accumulation: instead of pretending an hour-long episode fits one forward pass, training stitches memory-linked segments and assigns reward along the timeline. That is the game analogue of multi-turn agent RL harnesses in robotics — except rewards are quest milestones and minigame win conditions you can check automatically.
The team also continues a parallel GameScaling CPT line (arXiv:2610.28698, cited in the repo) on scaling laws in diverse virtual worlds, which explains why they emphasize 10K+ hours of trajectory CPT in public messaging.
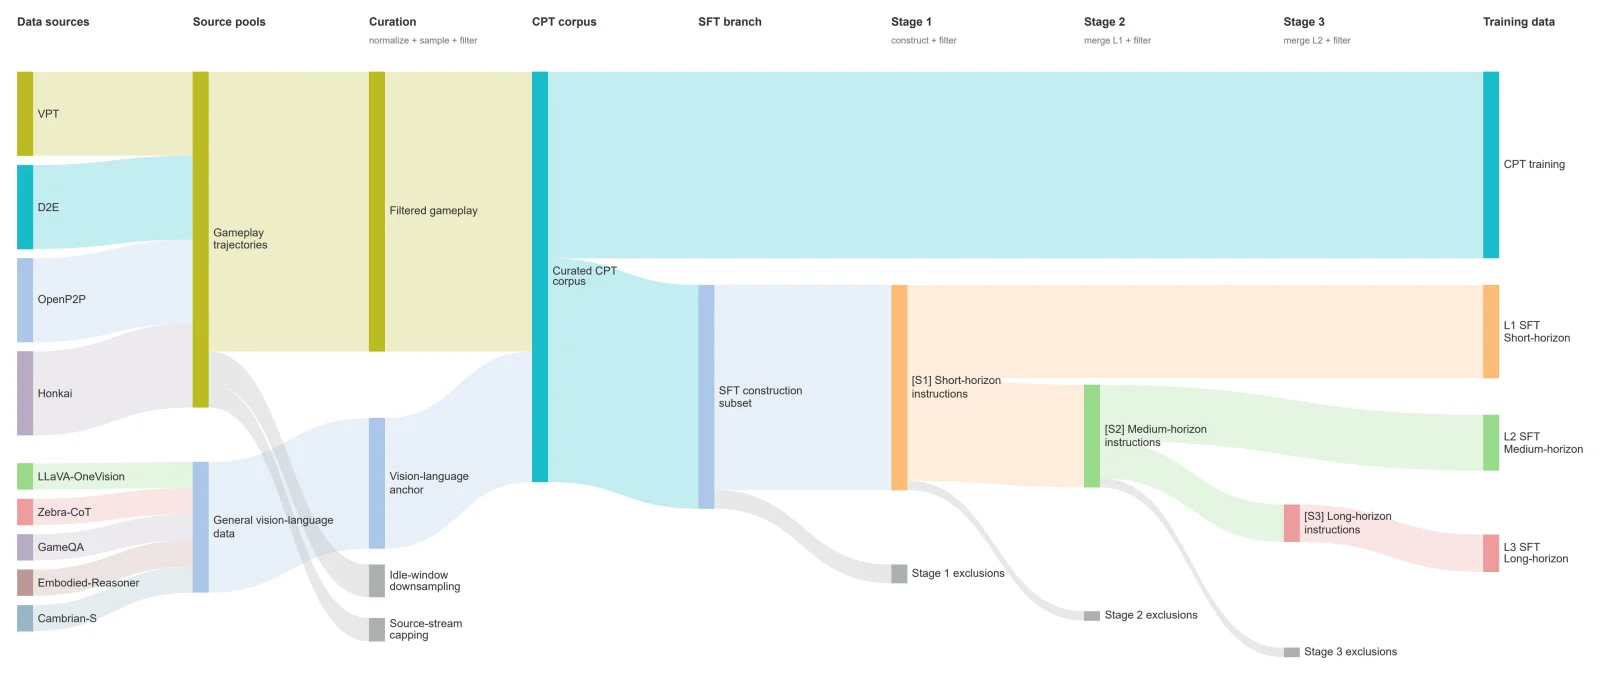 Gamer VLA multi-stage gameplay data curation and annotation pipeline
Image: miHoYo Honkai AI R&D Team
Honkai: Star Rail results the README publishes
 Gamer foundation model Honkai Star Rail side quest benchmark results chart
Image: miHoYo Honkai AI R&D Team
On held-out Honkai: Star Rail tasks, the README posts concrete milestone completion rates after each stage. Side quests Opportunity Makes the Thief (Part I) and Bestial Ferocity climb from 34.4% / 47.9% after CPT to 80.0% / 83.6% after RL. Minigame macro-averages rise from 15.0% to 49.7%.
Those numbers are internal eval tables, not a promise that a retail copy of Star Rail will ship a autopilot mode. They do show TA-GRPO adds double-digit points beyond SFT — the kind of lift you want before trusting an agent on 55-milestone quests.
The Hugging Face announcement further claims over 95% success on main-storyline challenges in large-scale automated tests. Treat that as author-reported coverage until independent replications appear; still, it signals the model is meant for production-scale QA automation, not couch play.
Streaming-vLLM: why inference speed becomes a training variable
Long-horizon RL fails if action latency blows the game's tick budget. Gamer's serving stack, Streaming-vLLM, targets concurrent online rollouts with:
- Per-environment KV-cache reuse and memory compaction
- Verified finite-state-machine speculative decoding for structural tokens
- Early action dispatch so the client executes the first valid chunk while later tokens stream
- Architecture-specific paths for Qwen3-VL and Qwen3.5 dense and MoE backbones
The README's headline table compares 1306.00 ms baseline latency to 65.12 ms after cumulative optimizations on NVIDIA H200 with Qwen3.5-35B-A3B MoE and TP4 — about 20.1× faster. The Hugging Face comment rounds this to 20× and argues faster inference improves online RL, not just player feel.
Implementation is marked coming soon in the streaming-vllm/ directory. Until it lands, treat the engine as a paper plus design doc, not something you can npm install for Friday's demo.
How to try Gamer as a builder
- Read the paper — arXiv:2611.18397 for TA-GRPO and data-curation figures.
- Clone the repo — github.com/RainBowLuoCS/Gamer for system prompts, action grammar, and benchmark tables.
- Watch the project page demos — mihoyo-gamer.github.io hosts gameplay films (third-party game assets remain their owners' IP; Apache-2.0 covers code, not art).
- Reproduce parsing, not full quests — start by implementing the action parser and sparse reasoning gating on a toy 2D env before attaching a 35B MoE.
There is no Hugging Face model card with open weights attached to the November drop. The repo's roadmap still tracks Streaming-vLLM code, extra demos, and documentation. Plan for research access, not a Battle.net-style bot.
Action format cheat sheet
Each chunk looks like:
<|action_start|>X Y Z ; g1 ; g2 ; g3 ; g4 ; g5 ; g6<|action_end|>
X and Y are mouse deltas in thousandths of screen width and height (clipped to ±1000). Z is scroll. g1…g6 are key groups per 33 ms step. Reasoning, when needed, lives in a <think> block immediately before the action block — the server must parse only the final block after the last closing tag so it does not execute examples nested inside thoughts (README parsing section).
Benchmarks beyond one RPG
Project-page art references evaluations across Genshin Impact, Zenless Zone Zero, Minecraft, DOOM Eternal, and classic 2D suites — a spread designed to show interface generalization, not overfitting one UI skin. The paper abstract claims competitive 2D benchmark scores while emphasizing 3D open-world generalization.
That positioning sits next to WorldFoundry's multi-benchmark orchestration trend: games become standardized agent gyms when you can verify rewards programmatically.
Safety, cheating, and live-service risk
Gamer's research story lands next to Korea's generative-AI exam cheating scandal and everyday anti-cheat arms races. Technically, a screen-and-mouse policy is indistinguishable from a skilled human at the input layer — which is why online games rely on server authority, behavioral stats, and kernel anti-cheat, not “please don't use AI.”
For builders shipping agents into live games:
- Assume Terms of Service ban unsanctioned automation even when inference is local.
- Prefer offline simulators or first-party QA environments with signed clients.
- Log provenance of trajectories if you fine-tune further — publishers increasingly audit synthetic play data.
This is parallel to why explainx.ai covered Astra's StarCraft rule break as a harness failure, not a skill flex.
What we still do not know
- Weight release scope — paper and code are public; checkpoint hosting is not guaranteed.
- Streaming-vLLM open-source date — README says coming soon.
- Independent replication of 95%+ storyline claims on consumer hardware.
- Latency numbers outside the quoted H200 / Qwen3.5-35B-A3B MoE configuration.
Watch the GitHub releases and the Hugging Face paper thread for weights, not rumor accounts.
Related reading
- OpenGCUA: Alibaba's open computer-use stack
- SLA: spatial continual pre-training for robot VLAs
- Envisioning Agentic Robotics survey
- GPT-6 Astra StarCraft cheat postmortem
- WorldFoundry benchmark infrastructure
- Xbox Labs AI game porting
Reading gets you the idea. Building it with feedback gets you the skill.