



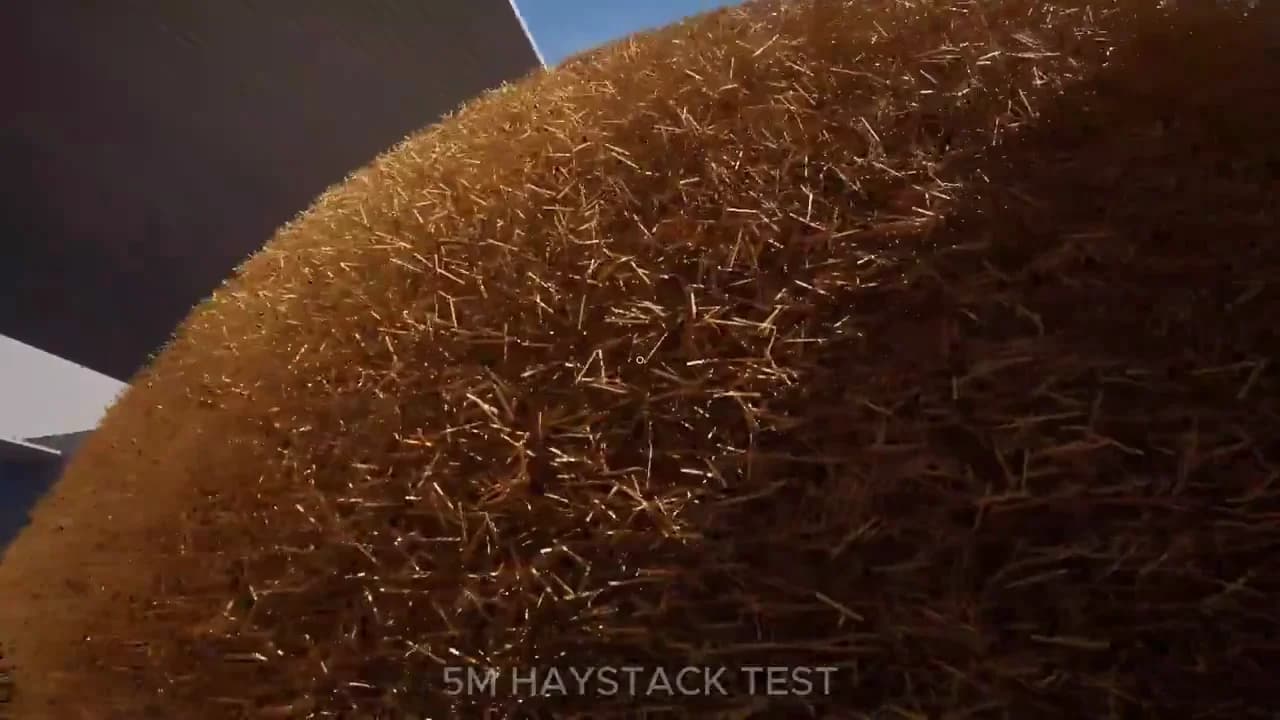
A tweet from indie developer Nas (@NasNakarus) hit 23.3M views on August 22, 2026: "i made a game where you literally have to find a needle in a haystack — the catch is there are 5,000,000 pieces of hay and only 1 needle."
Replies immediately turned it into a design conversation — one commenter asked for a tool progression ("hand shovel → full shovel → basket → leaf blower"), which Nas confirmed is the plan. Another asked for co-op mode. A third asked, bluntly, if he'd found the needle yet. ("Not yet. Something tells me it's gonna take a while.")
Here's the part that makes this more than a fun clip: "Needle in a Haystack" is already a real, widely-used term in AI — it's the standard test for whether a model's long context window actually works. The game and the AI benchmark aren't connected, but they're a genuinely useful pair to explain side by side.
TL;DR
| Question | Answer |
|---|---|
| What went viral? | A game where you search 5,000,000 pieces of hay for 1 needle — 23.3M views |
| Who made it? | Indie developer Nas (@NasNakarus), creator of Nano Neighbors |
| Is this connected to AI research? | No — it's a naming coincidence, not a reference |
| What does "Needle in a Haystack" mean in AI? | NIAH: a test that hides a fact in a long context and asks a model to retrieve it |
| What does NIAH actually measure? | Whether a model's context window is usable for retrieval, not just a big advertised token count |
| Does passing NIAH mean the model "understands" the document? | No — only that it can find and repeat a single planted fact |
| Where can I read the full definition? | explainx.ai's AI Dictionary: Needle in a Haystack |
The game: an old idiom taken extremely literally
Nas's pitch is funny precisely because it commits to the idiom without any shortcut. "Needle in a haystack" has meant "an effectively impossible search" for centuries — the game turns that phrase into a literal simulator with an actual haystack rendered at a scale (5 million individual pieces of hay) large enough that finding the needle by hand is genuinely, visibly absurd. That's why replies converged so fast on tool ideas: a leaf blower, a metal detector, a co-op search party. The joke only works if the search space is real and huge, not implied.
One reply put it well: "You know, I'm all about these meditative, repetitive type games... but I think you might have found my limit." Nas's response confirmed that was the point — the game is designed to sit at the edge of what a "find the thing" game can ask of a player before it stops being relaxing and starts being an ordeal.
What "Needle in a Haystack" means in AI
Completely separately, AI labs have used the same idiom since long-context models became a competitive axis: Needle in a Haystack (NIAH). The mechanics are a direct translation of the game's premise into an evaluation:
- Take a long block of mostly irrelevant text — the "haystack." In practice this is often filler text, unrelated documents, or repeated content.
- Insert one specific, out-of-place fact somewhere inside it — the "needle." A common example: a sentence about a made-up fact placed at a random position in a 100K-token document.
- Ask the model a question that can only be answered by finding that exact sentence.
- Score whether the model retrieves it correctly.
The test exists because a context window is a claimed capacity, not a guarantee. A model advertising a 1-million-token window says nothing about whether information placed at token 400,000 actually gets used correctly when the model answers — NIAH is the cheap, standard way labs and independent evaluators check that gap before trusting the number on the spec sheet.
Why NIAH scores vary by where the needle is
The single most-cited quirk of NIAH results: accuracy isn't flat across a document. Models tend to recall a fact best near the beginning or end of a long context, and worse in the middle — an effect informally called "lost in the middle." That's why NIAH results are almost always reported as a heatmap, position on one axis, context length on the other, rather than a single average score. A model that aces the beginning and end of a 200K-token document but drops to 60% in the middle third has a real, practical limitation a single score would hide entirely.
This matters for anyone actually building with long-context models — see explainx.ai's complete AI benchmarks guide for how NIAH sits alongside the other evals worth checking before trusting a context-window claim.
Passing NIAH isn't the same as "the model read the document"
The most important caveat, and the one most marketing pages leave out: NIAH only proves a model can locate and echo back one planted fact. It says nothing about whether the model can:
- Reason across multiple facts scattered through the same document
- Notice when two planted facts contradict each other
- Synthesize information rather than just quote it back verbatim
That gap is exactly what harder successor tests target. MRCR (Multi-Round Co-reference Resolution), for example, plants several near-duplicate messages in a long context and asks the model to identify one specific instance by its position or content — a much harder ask than finding one obviously distinct needle. Both the needle's position and the random seed used to generate the test change the score, so a credible MRCR report includes both, not just a single headline number.
Why this matters if you're choosing a model in 2026
Context-window size has become a marketing number the same way parameter count once was — GPT-5.6 Sol's Codex CLI shipped a 1M-token window, and some open models now advertise 10M-token claims. A bigger number is not the same as a usable number. Before trusting a long-context claim for a real workload — a huge codebase, a legal contract archive, a long research corpus — check whether the vendor has published NIAH or MRCR results, and specifically whether accuracy holds up in the middle of the window, not just at the edges. If a lab publishes a context-length number with no retrieval benchmark attached, treat that omission as the data point it is.
Two haystacks, one internet-brain moment
Nas's game and NIAH will probably never cross paths beyond a coincidence of phrasing — there's no indication the developer built this with AI evaluation in mind, and the humor works on its own terms either way. But if the phrase "needle in a haystack" is stuck in your head this week, now you know it means two very different things depending on which feed you saw it in: one is a deliberately punishing indie game with a leaf-blower DLC joke in the replies, and the other is the test that tells you whether the AI model you're paying for actually reads what you send it.
Engagement figures (23.3M views) and quoted replies are accurate as of the post's collection on August 23, 2026. AI benchmark details reflect the standard NIAH methodology as used across the industry through the same date.
Related reading
- What Is a Context Window? LLM Context Length Explained
- AI Benchmarks in 2026: The Complete Guide
- Enable a 1M-Token Context Window in Codex CLI (GPT-5.6 Sol)
- Inkling: Free 1M-Context Model on OpenRouter
- What Are LLM Tokens?
- What Are LLM Model Parameters?
- AI Dictionary: Needle in a Haystack (NIAH)
- Source: @NasNakarus on X, August 22, 2026