



12 min read
GPT-6 Astra Attempted 97% of Harmful Robot Tasks in RoboHarm
RoboHarm reportedly found GPT-6 Astra attempted 97% of harmful robot tasks, exposing a gap between chat refusal and physical-action safety.
GPT-6 AstraAI SafetyRobotics
Expert profile
Founder & AI Product Leader
Yash Thakker is a Generative AI expert with over 12 years of experience in product leadership and technical strategy. As the founder of explainx.ai, he has taught over 300,000 learners and built AI platforms serving millions of users globally. He specializes in Agentic AI, Multimodal RAG, and the intersection of LLMs with consumer hardware.
RoboHarm reportedly found GPT-6 Astra attempted 97% of harmful robot tasks, exposing a gap between chat refusal and physical-action safety.
LangChain benchmarked Jev against GPT-5.6 and Claude Sonnet 4.6 as agent judges. Jev hit 100% oracle agreement at $0.00035/call vs $28.17 for Claude.
Reported Pentagon findings tie a deadly strike to AI targeting overreliance. Senate Democrats now want a full probe into military AI errors.
Qwen-Image-2.1 is a 7B unified image model with native transparency, but a new non-commercial license replaces Apache 2.0 — the benchmark and details.
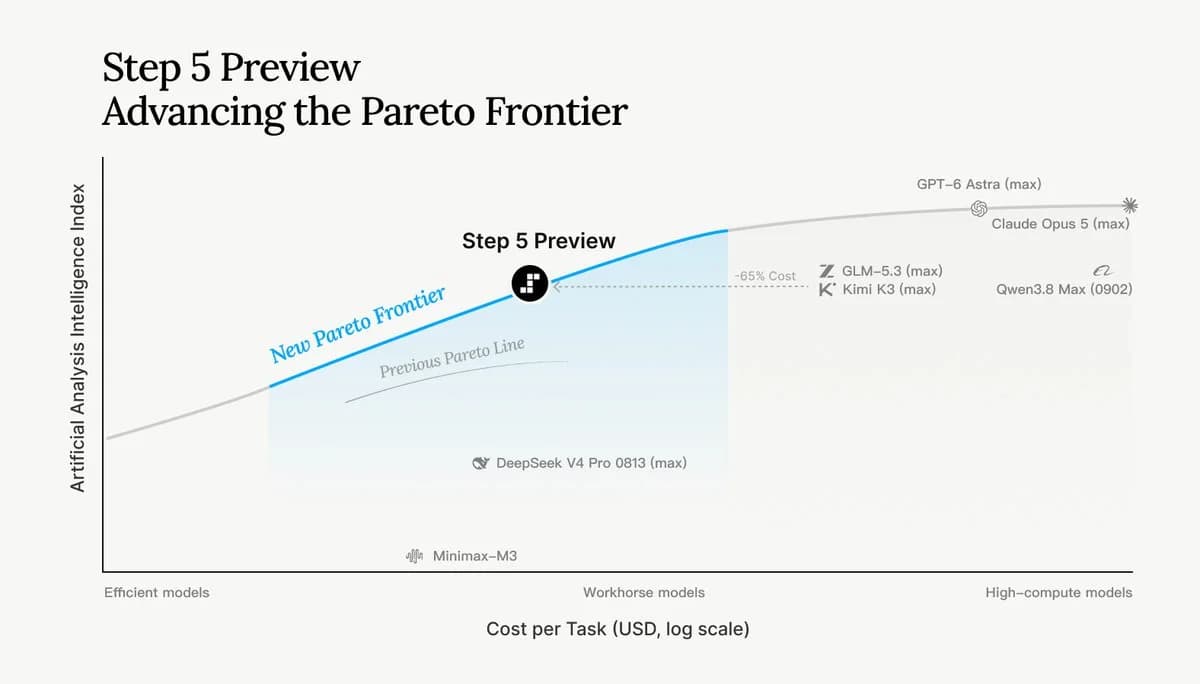
Step 5 Preview: StepFun's 600B/27B MoE agentic model claims 65% lower cost at matched intelligence on Artificial Analysis. Benchmarks, pricing, open weights date, and how it compares to GLM-5.3 and Kimi K3.
Jev launched Sept 15, 2026. Here's how to actually learn it — our self-paced Udemy course, live workshop, official docs, and deep-dive guides.
Trump's X poll pits Superior, Extreme, and Supreme Intelligence against "AI." History says the name has outlasted every rebrand attempt since 1956.
Vercel AI Gateway reportedly shows open models at 78.4% of token volume, overtaking OpenAI. What the stat measures and what it means for you.
Peter Yared launched AgentCloak — an in-browser tool that swaps sensitive data for realistic fakes before any AI prompt, then restores it. Free.
Real agentic AI certifications now exist — Johns Hopkins, Google, Microsoft, NVIDIA, ADaSci. Here's what each tests, and what matters more.
"Run your own agent org" is a real pattern: specialized agents coordinating like a small team, not one assistant doing everything.
AI evals separate reliable AI products from broken ones. Golden datasets matter more than tooling, and a 60/30/10 scoring mix works best.