



AWS has published part 2 of its 2026 SageMaker inference review, adding 13 launches (numbers 14 to 26) and bringing the year's total to 26. The November 19, 2026 post, Amazon SageMaker Inference: 2026 launches in review, part 2, follows one fictional support team from a single 70B-parameter endpoint to multi-Region serving, and groups the launches by the problem they solve.
This is a vendor review, so the numbers are AWS's own. We separate what each launch does from the performance figures AWS attaches to it. Several of these features already have their own explainx.ai posts, linked below.
TL;DR: the 13 launches at a glance
| # | Launch | Date | What it does |
|---|---|---|---|
| 14 | Inference recommendations in SageMaker AI Studio | July 2026 | Guided, low-code benchmarking and ranked configurations |
| 15 | Recommendations in Python SDK v3 | August 2026 | Benchmark, recommend and deploy from notebooks or pipelines |
| 16 | LoRA adapter support in recommendations | September 2026 | Benchmarks adapter count against concurrency |
| 17 | SLA-based concurrency search | September 2026 | Finds the highest concurrency that meets latency and error targets |
| 18 | Agent skill for inference | October 2026 | Instance selection and benchmarking from coding agents |
| 19 | Inference Components in the console | October 2026 | Create, scale and monitor each model without scripts |
| 20 | GPU partitioning with NVIDIA MIG | October 2026 | Up to seven isolated partitions per GPU |
| 21 | Managed NVIDIA Dynamo on HyperPod | November 2026 | Multi-node and disaggregated serving, operated by HyperPod |
| 22 | KV-cache-aware routing | November 2026 | Routes to the instance holding the longest cached prefix |
| 23 | HyperPod Inference Gateway | September 2026 | One OpenAI-compatible endpoint per cluster, GPU-aware routing |
| 24 | Cross-Region Inference Router | not dated | Routes across Regional and cross-account endpoints |
| 25 | Continuous performance monitoring | November 2026 | Detects latency drift, configuration gaps, idle GPUs |
| 26 | In-place rolling model updates | November 2026 | Updates a fleet with one batch of extra instances |
Stage 1: choosing a configuration (launches 14 to 18)
AWS's example team picked its first configuration from an April benchmark. Since then it added four LoRA adapters and set a 500-millisecond target for time to first token (TTFT) at peak load. The old benchmark never tested either change.
The Studio workflow lets you choose a use-case profile (Interact, Generate, Summarize or Custom), a goal (minimise latency, maximise throughput or minimise cost) and a model from JumpStart, Amazon S3, the Model Registry or an existing model. AWS says SageMaker benchmarks candidates on real GPU infrastructure with NVIDIA AIPerf and applies techniques such as speculative decoding for throughput or kernel tuning for latency. Results come back ranked by TTFT, inter-token latency, throughput and cost.
Two additions are the most practical. LoRA support accepts adapters as Model Package ARNs or S3 URIs, including adapters from Hugging Face PEFT, and recommends deploying them as separate inference components so you can add or remove one without touching the base model. The SLA-based search takes a search_recipe of max-concurrency-under-sla plus targets for TTFT, time per output token, end-to-end latency and error rate, and returns the largest passing concurrency (feasible_max) or the smallest failing one (infeasible_min). That replaces manual sweeps.
The agent skill, aws-ai-ml in the Agent Toolkit for AWS, gives coding agents such as Kiro SageMaker inference knowledge. AWS says setup takes about 10 minutes and it works with any agent that supports the Model Context Protocol. For background on that protocol, see our MCP guide.
Stage 2: fitting more models on each GPU (launches 19 and 20)
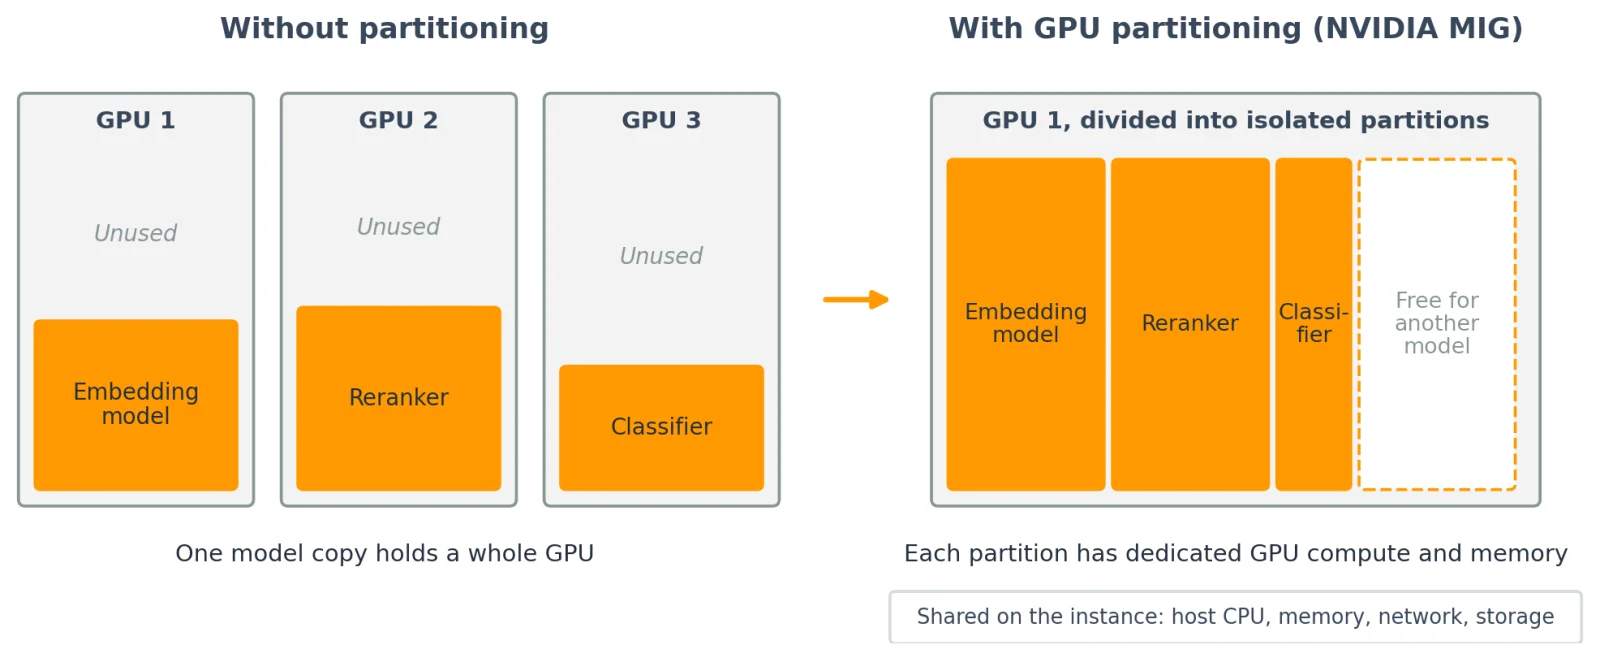 SageMaker inference launches: three small models sharing partitions of one GPU with MIG
Image: AWS
The team also runs an embedding model, a reranker and a small classifier that each use a fraction of a GPU. Inference Components, which host several models on one endpoint, now appear in the SageMaker AI console. You can create and edit components, set an automatic scaling policy per component down to zero copies, and see per-component alarms and metrics.
MIG divides one physical GPU into as many as seven partitions with dedicated compute and memory and hardware isolation. Applications still invoke models by inference component name. The caveat matters for budgeting: models on one instance still share host CPU, host memory, networking, storage and endpoint routing, and you pay the standard rate for the full instance-hour. The saving is in placement, not in price. We covered this in SageMaker Inference Adds NVIDIA MIG.
Stage 3: serving models larger than one instance (launches 21 to 23)
When a reasoning model's weights exceed any single instance's GPU memory, AWS moves the workload to HyperPod Inference. Three launches apply.
Managed NVIDIA Dynamo gives multi-node and disaggregated serving with HyperPod operating the platform underneath. For the engine itself, see NVIDIA Dynamo and KV-aware routing for RL rollouts.
KV-cache-aware routing has the container publish cache creation and eviction events to a central index, and SageMaker routes each request to an eligible instance holding the longest matching cached prefix. It works with single-model endpoints and inference components, including LoRA adapters, and supports InvokeEndpoint, InvokeEndpointWithResponseStream and the OpenAI-compatible Completions and Chat Completions payloads. The first release requires an AWS-verified container. Prefix-aware routing, from part 1, needs no container changes. Read our deeper post on KV-cache-aware routing for vLLM endpoints and the explainer what is a KV cache.
The HyperPod Inference Gateway installs with the Inference Operator add-on and gives each cluster one OpenAI-compatible endpoint for all models. It weighs KV cache utilisation, queue depth, running requests, prefix cache hit rate and LoRA adapter residency. AWS says it cut P99 TTFT by up to 97% on mixed GPU generations and up to 98% under bursty traffic versus round-robin. Those are AWS's own comparisons against the weakest baseline, so expect smaller gains against a tuned router.
Stage 4: routing across Regions (launch 24)
The Cross-Region Inference Router groups endpoints that serve the same model under one routing target, in the same or different accounts. It tries the local endpoint first and moves traffic when it cannot serve a request. It does not add capacity, replicate models or deploy endpoints. Traffic uses AWS PrivateLink with cross-account authorisation, the endpoint owner can cap overflow traffic, and the application can restrict which Regions may serve a request. See SageMaker Cross-Region Inference Routing for the failover details. AWS's own post on the feature is here.
Stage 5: keeping endpoints tuned (launches 25 and 26)
Two months after the team adds retrieval, average prompt length roughly doubles and TTFT rises, yet no alarm fires. Continuous performance monitoring catches this class of problem. AWS says it is on by default with no setup and opt-out per endpoint, looks only at latency, GPU utilisation and serving configuration, not your requests or responses, and reports three finding types: latency drift after a traffic change, a configuration gap present since deployment, and idle GPU capacity. Nothing deploys until you apply it.
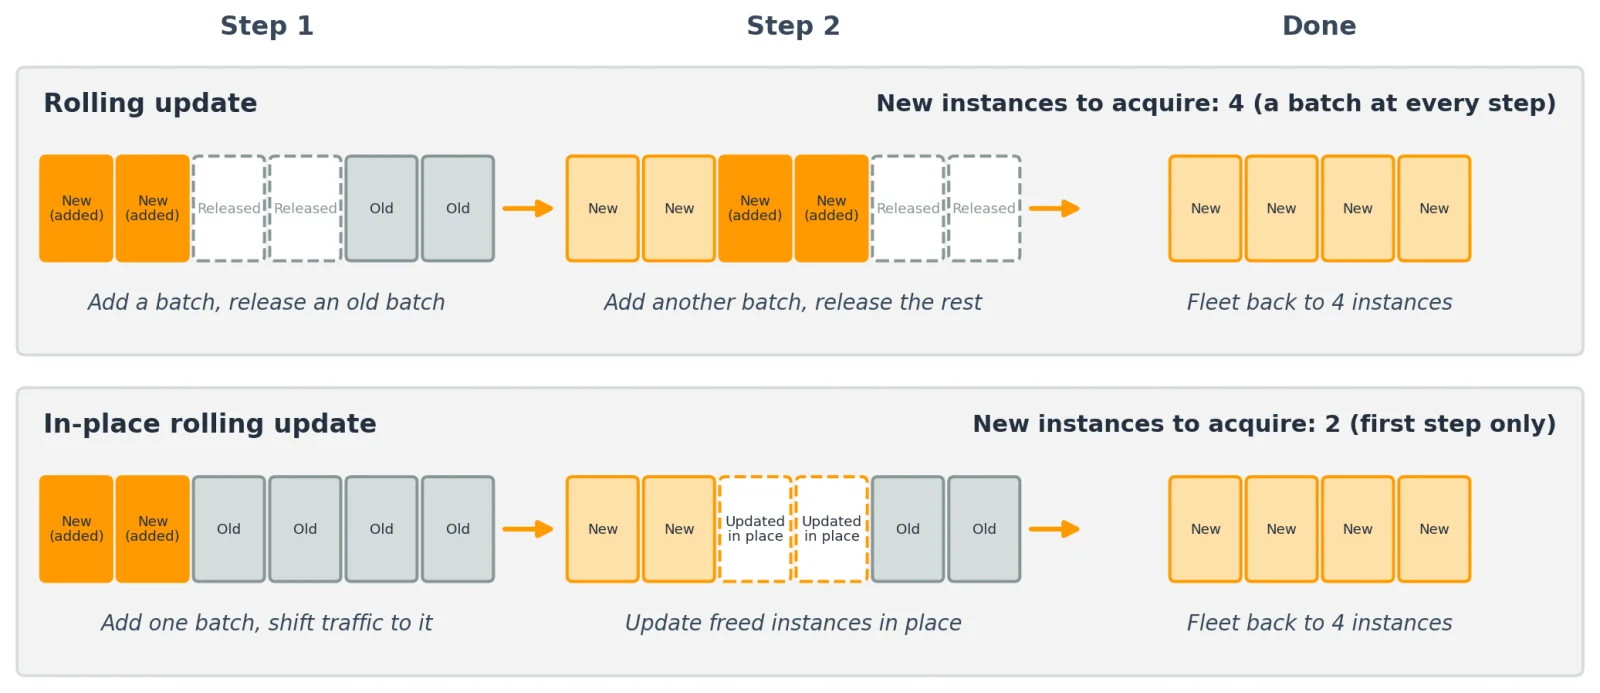 In-place rolling update reusing the fleet instead of acquiring new GPU instances at every step
Image: AWS
In-place rolling updates attack a different pain: a standard rolling update finds new capacity at every step, and can fail partway when the next batch of GPU instances is unavailable. AWS now provisions one small batch, shifts traffic, and reuses freed instances. With 20 instances and batch size 2, AWS says the update acquires 2 new instances instead of 20. AWS plans scale-in-first updates in early 2027 that would remove the need for any extra instances.
Which launches matter for which reader?
| If you are... | Look first at |
|---|---|
| Running one LLM endpoint with traffic that has changed | Recommendations with SLA search (17) and monitoring (25) |
| Hosting many small models | Inference Components console (19) and MIG (20) |
| Serving a model too big for one instance | Managed Dynamo (21), KV-cache routing (22), Inference Gateway (23) |
| Short of GPU capacity in one Region | Cross-Region Router (24) and in-place updates (26) |
| A coding-agent user | The aws-ai-ml agent skill (18) |
What is verified and what is AWS's claim
The feature descriptions come from AWS's own post and linked developer documentation. The performance figures (97% and 98% lower P99 TTFT, 2 versus 20 instances) are AWS's examples. We have not run them. The review is also a marketing roundup: it ends by pointing to the AWS Experience-Based Acceleration program. Treat the list as a map of what exists, then test each feature on your own workload. Pricing details sit on the SageMaker pricing page.
For related AWS inference and agent work, see SageMaker HyperPod enhanced observability and SageMaker fine-tuning with serverless customization.
What teams are asking
Do I need to change client code for MIG? AWS says applications keep invoking models by inference component name, so client code does not change.
Does cross-Region routing replicate my model? No. You must already have endpoints deployed; the router only sends traffic between them.
Will in-place updates need a config change? AWS says customers do not need to change anything.
Related reading
- SageMaker Inference Adds NVIDIA MIG
- SageMaker KV-cache-aware routing for vLLM endpoints
- SageMaker Cross-Region Inference Routing
- SageMaker HyperPod enhanced observability
- NVIDIA Dynamo and KV routing for RL rollouts
- What is a KV cache?
- What is MCP?
Launch names, dates and figures are as stated in AWS's November 19, 2026 post and may change.