



Amazon SageMaker AI Serverless Model Customization now supports Full Fine-Tuning (FFT), not only parameter-efficient LoRA adapters. AWS published the workflow on November 18, 2026, arguing FFT can close quality gaps on large, complex corpora when LoRA plateaus.
For builders on Bedrock AgentCore or custom model routes, the headline is operational: one serverless job type now spans cheap adapters and full-rank updates without a separate training stack.
FFT versus LoRA in plain language
LoRA freezes base weights and trains small low-rank matrices. It saves GPU memory and trains fast. AWS warns that low-rank updates can cap representation power as tasks grow—extra rank does not always catch up to full fine-tuning.
FFT updates all parameters together. AWS says that preserves layer alignment better on complex domain shifts, especially when datasets exceed tens of thousands of high-quality examples.
| Method | Memory | Best when | Risk AWS highlights |
|---|---|---|---|
| LoRA | Lower | Smaller shifts, budget fine-tunes | Rank plateaus on hard tasks |
| FFT | Higher | Large curated corpora, code style absorption | Catastrophic forgetting at aggressive LR |
This is not an either-or religion. AWS's own charts show LoRA winning one LLM-as-Judge comparison while FFT wins aggregate PRIMECODE and large-scale judge scores.
The November 18 experiment design
AWS ran supervised fine-tuning on Qwen3-4B using Magicoder-Evol-Instruct-110K—110,000 coding instruction pairs spanning algorithms, debugging, and systems topics. Split:
- 99,000 train
- 5,500 validation
- 5,500 held-out test
Jobs ran on SageMaker AI Serverless Model Customization with identical prompts and evaluation code for LoRA and FFT branches.
Code entry point
AWS sample code constructs SFTTrainer with TrainingType.FULL:
from sagemaker.train.sft_trainer import SFTTrainer
from sagemaker.train.common import TrainingType

trainer = SFTTrainer(
    model=base_model_id,
    training_type=TrainingType.FULL,
    model_package_group=model_package_group_name,
    training_dataset=training_dataset,
    validation_dataset=val_dataset,
    s3_output_path=output_path,
    sagemaker_session=sess,
    role=role,
)

trainer.hyperparameters.learning_rate = 2e-5
trainer.hyperparameters.global_batch_size = 8
trainer.hyperparameters.max_epochs = 2
trainer.hyperparameters.lr_warmup_steps_ratio = 0.1

trainer.train(wait=False)
Switching to LoRA is TrainingType.LORA only—everything else unchanged per AWS.
Fine-tuned artifacts register as versioned Model Packages in the SageMaker Model Registry when jobs complete.
Evaluation trio AWS ships serverlessly
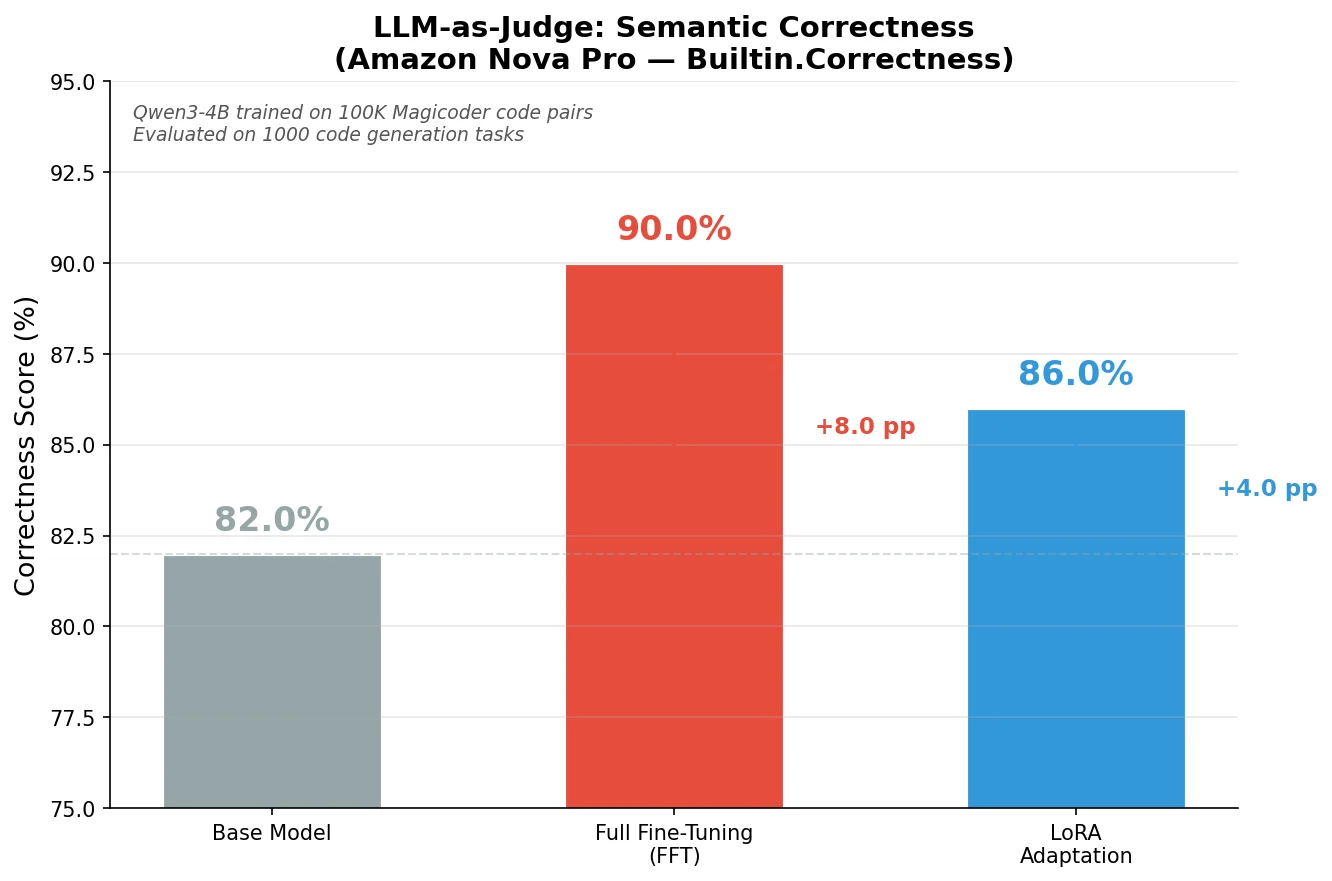 LLM-as-Judge semantic correctness FFT versus LoRA at 100K examples
Image: Amazon Web Services
AWS evaluates inside the same serverless product:
- LLM-as-Judge — Amazon Nova Pro judges whether generated code is logically correct versus the prompt.
- PRIMECODE — Deterministic BLEU, ROUGE, and F1 against reference solutions for reproducible code-style metrics.
- MMLU — Forgetting detector across 57 academic subjects; tracks whether code fine-tuning erases general knowledge.
At 100K+ scale AWS charts ~90% LLM-as-Judge semantic correctness for FFT on the coding task setup they describe. Radar charts show FFT extending farther than LoRA across multiple quality axes in the same post.
Caveat: Those figures are AWS-run benchmarks on a single public dataset. Replicate on your validation set before production routing.
Hyperparameters AWS sweeps
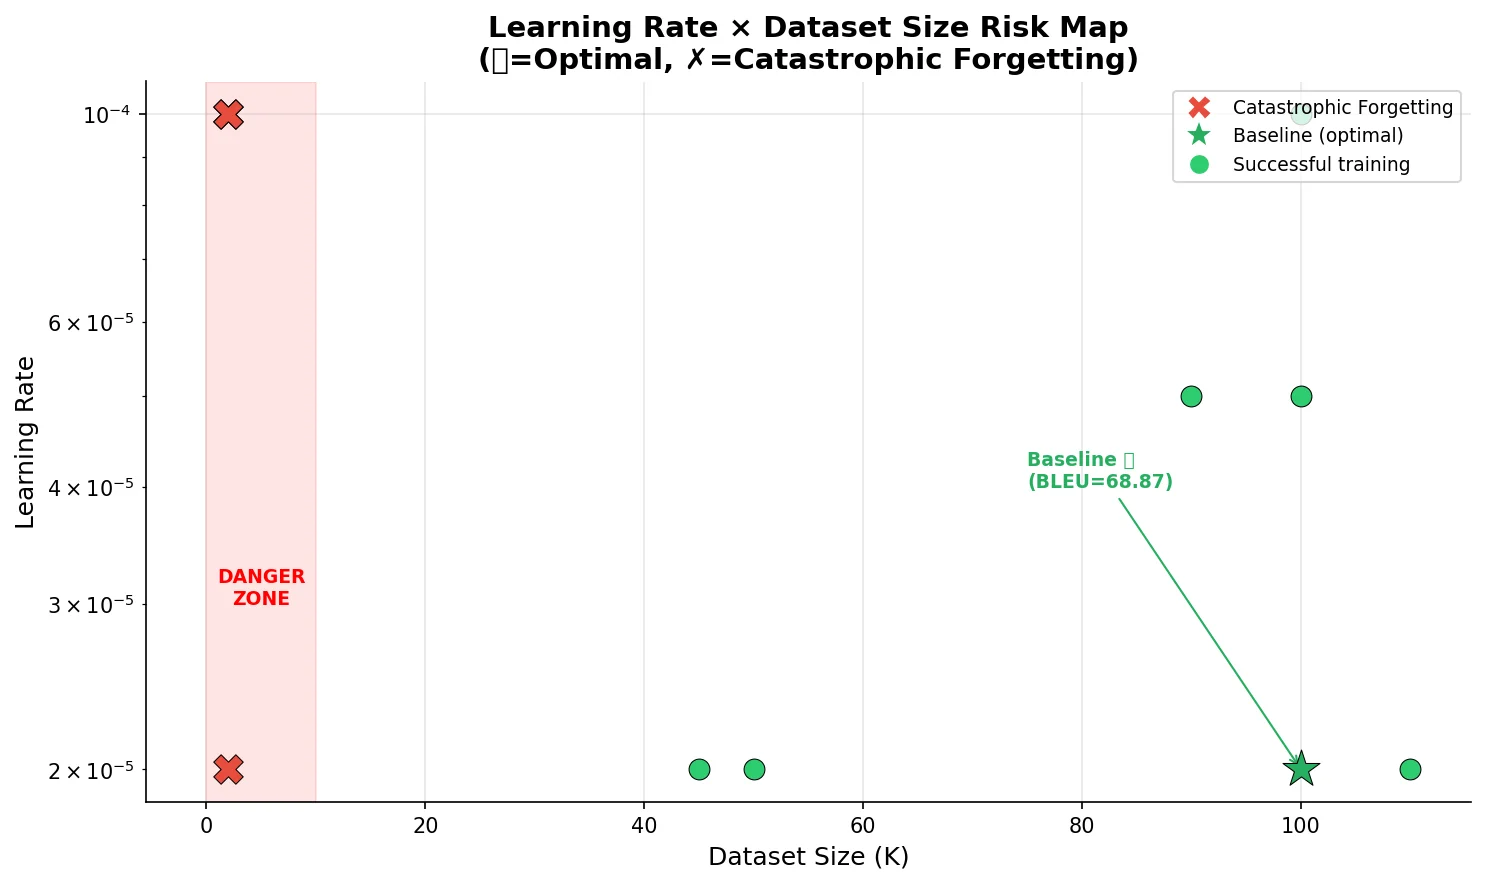 Learning rate dataset size risk map for SageMaker full fine-tuning
Image: Amazon Web Services
Learning rate
FFT touches every weight. AWS maps learning rate × dataset size risk: 2e-5 at 100K+ examples landed in their safe zone. ≥5e-5 wrecked MATH exact match and drove MMLU toward ~3.6% in aggressive configs—classic catastrophic forgetting.
Epochs
AWS treats max epochs as a forgetting knob, not a loss-curve game. ~3 epochs raised judge scores toward 90%, but beyond 3 degraded variants they tried—even when validation loss still looked fine on in-distribution code.
Batch size
Smaller batches add noise akin to higher LR; larger batches smooth updates but reduce steps. AWS includes batch-size trade-off charts in the post.
Warmup
A configuration with 5% warmup, batch size 8, and LR 2e-5 best preserved MMLU in their forgetting study.
When AWS says to stay on LoRA
The post is explicit FFT is not universal:
- Both FFT and LoRA trailed the base model on MATH exact match in some runs.
- LoRA at 81.5% beat FFT at 79.5% on one LLM-as-Judge setup AWS lists.
- Aggressive FFT schedules destroyed general benchmarks.
Pick FFT when you have large, clean in-domain data and monitoring for MMLU-style drift. Stay on LoRA when budgets, iteration speed, or subjective judge alignment matter more.
How this compares to other serverless trainers
| Platform | Full-weight SFT serverless | Notes |
|---|---|---|
| SageMaker (this launch) | Yes, TrainingType.FULL | Bundled judge + PRIMECODE + MMLU |
| Baseten Loops | SFT and RL per token | Different billing model |
| Snowflake Cortex Training | Preview SFT and RL | Warehouse-adjacent |
SageMaker's angle is enterprise registry + evaluation batteries in one managed lane—valuable if you already standardize on AgentCore identity.
Builder checklist for this week
- Inventory data size. Below ~10K curated examples, start LoRA; plan FFT trials when growth toward 100K is realistic.
- Pin evaluation. Export baseline MMLU and domain-held-out sets before first FFT job.
- Cap LR at AWS's 2e-5 starting point unless your regression suite proves otherwise.
- Stop at epoch 3 until you see forgetting curves flatten safely.
- Register packages in Model Registry for rollback when coding model scores rise but merge rates fall.
Spectral view: why AWS says rank limits LoRA
The AWS post dives into weight matrix spectra: LoRA applies a low-rank delta that cannot express every direction full fine-tuning can move. As datasets scale, the missing directions show up as plateaus in judge scores even when you increase LoRA rank.
FFT modifies matrices uniformly, which AWS ties to better activation alignment across layers. You do not need to accept the theory wholesale to use the practical signal: when validation loss stalls while train loss falls on LoRA, FFT is the next serverless knob—if your MMLU guardrail passes.
Rapid experimentation story
AWS emphasizes tens of jobs in a short window because serverless removes cluster babysitting. They swept:
- Training type (FFT vs LoRA)
- Learning rate, batch, warmup, epochs
- Base models: Qwen3-4B, DeepSeek-R1-1.5B, Nemotron-30B, Gemma-4-26B
Each job registered outputs in Model Registry, so promotion to endpoints stays auditable—important when audit agents ask for lineage.
PRIMECODE versus LLM-as-Judge
PRIMECODE rewards n-gram overlap with reference solutions—great for detecting formatting conventions and API usage patterns in code corpora. LLM-as-Judge rewards logical correctness from Nova Pro's reading of the prompt plus code.
AWS uses both because neither alone is sufficient: a solution can look like the reference yet be wrong, or be correct yet novel. If you only track loss, you miss the split.
Operational details builders ask in search
Do I provision GPUs? AWS says no—serverless customization allocates compute for the job.
Where do checkpoints live? S3 output paths you provide; registered packages surface in Model Registry.
Can I A/B in production? Use packages as versions; pair with higher merge-rate experiments before routing traffic.
What about RL after SFT? This post covers SFT only; combine with your RL stack separately—compare MIT agent self-improvement loops if you chain RL after FFT.
Failure modes to log in your runbook
- MMLU cliff after epoch 3 — roll back package, reduce LR, or shorten epochs.
- Judge regression vs base on subjective tasks — LoRA may be the better tool per AWS's own tie cases.
- MATH exact match collapse — treat as forgetting alarm, not noise.
- Cost spikes — FFT uses more compute than LoRA; watch job duration against TSMC credit stories only if you finance GPU-hours centrally.
Enterprise procurement angle
Teams already buying SageMaker for compliance get FFT without a separate vendor. That matters when Snowflake and Baseten compete on per-token economics but your IAM boundary is AWS-only.
Document Nova Pro judge costs in FFT evaluation—they are not free tokens even when training is serverless.
Step-by-step first FFT job
- Register Magicoder or your corpora in SageMaker dataset assets.
- Create a model package group for promotion discipline.
- Instantiate SFTTrainer with
TrainingType.FULLand conservative LR 2e-5. - Run MMLU baseline on the base package before training.
- Train with max_epochs=2 first; inspect PRIMECODE and judge on held-out code.
- Compare against a LoRA twin job on identical splits.
- Promote only if MMLU drop sits inside your risk tolerance.
Documentation pointers
AWS links hyperparameter docs for Serverless Model Customization on the SageMaker doc site—read those alongside this post for field names that change release to release. The blog date is November 18, 2026; if your account lacks TrainingType.FULL, your region may still be rolling out—open a support case rather than assuming the blog is wrong.
For dataset hygiene, Magicoder-Evol-Instruct is a public corpus tied to the Magicoder paper on OSS-Instruct and Evol-Instruct data; enterprise teams should mirror the 90/5/5 split discipline on proprietary logs with PII stripped, similar to how GitHub and Microsoft m-dash reports stress provenance before automation.
Cost realism
Serverless does not mean free. FFT updates more parameters per step than LoRA, so expect longer jobs and higher GPU-second bills even without cluster admin overhead. Model the inference savings only after you measure quality uplift on your held-out suite—do not assume FFT inference is cheaper; you may deploy a smaller specialized model that beats a frontier generalist on your task, which is the economic story AWS tells at the top of its post. Keep a LoRA checkpoint as rollback until FFT wins on your judge suite twice in a row.
Related reading
- Baseten Loops serverless SFT
- Snowflake Cortex training preview
- AWS Bedrock AgentCore identity
- Higher scoring models and merge rates
- Qwen38 OpenCode adapter LoRA
Benchmarks and charts come from the AWS Machine Learning Blog post dated November 18, 2026; rerun on your data before production commits. Contact AWS support if TrainingType.FULL is missing in your account region.