



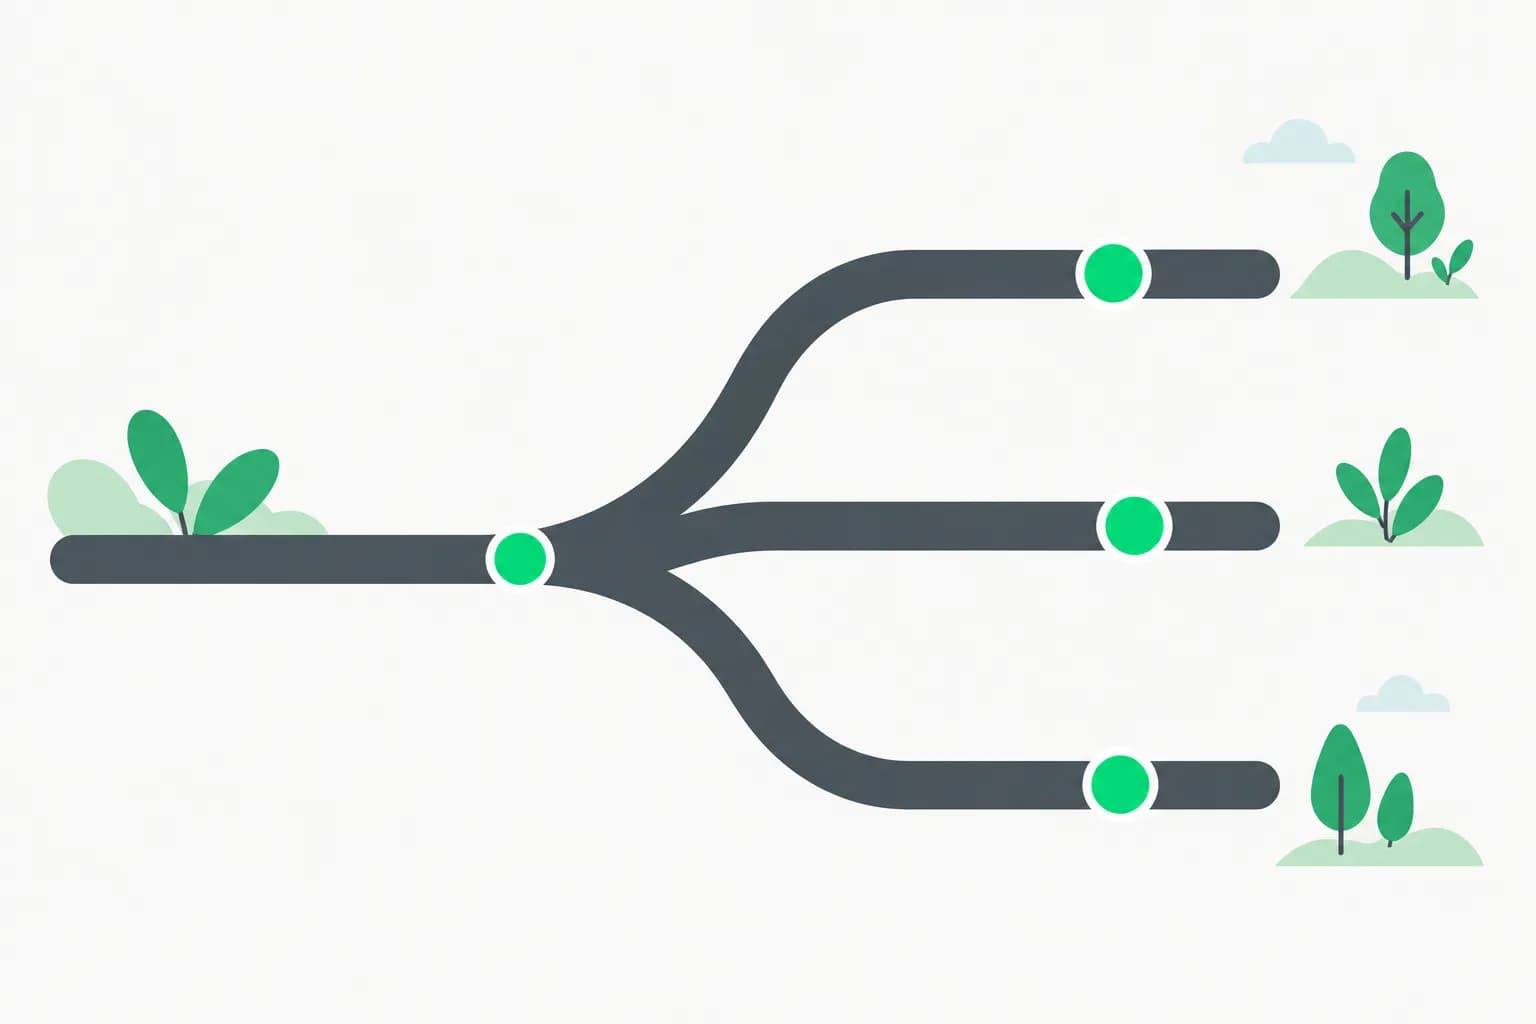
Prime Intellect has added filesystem checkpointing to Prime Sandboxes. A Prime Intellect-linked post on X summarized the feature as the ability to "fork new rollouts from any intermediate state, then checkpoint inside a branch and fork again to dig deeper." The company's sandbox documentation confirms the feature and spells out how it works, what it saves and what it costs.
If you run coding agents or agentic reinforcement learning (RL), the pitch is simple: stop replaying the first 40 steps of a trajectory every time you want to try a different 41st step.
Prime Sandboxes checkpoints at a glance
| Question | Answer (per Prime's docs) |
|---|---|
| What is saved? | The sandbox filesystem only |
| Processes and memory? | Not saved; forks start with fresh processes |
| Fastest way to branch? | prime sandbox fork sbx_123 --name experiment-branch --yes |
| Keep one for later? | prime sandbox checkpoint create, then checkpoint restore |
| When is it usable? | Once its state is DURABLE |
| Storage price | $0.10 per GiB per month, billed hourly |
| One-time charge | One day of storage when the checkpoint becomes DURABLE |
| Sandbox rates | $0.02 per vCPU hour, $0.0125 per GiB memory hour, $0.0002 per GiB disk hour, valid through December 22, 2026 |
| Needs | VM sandboxes (the docs list checkpoints under VM sandboxes) |
What a checkpoint is, and is not
Prime Sandboxes are disposable, isolated microVMs for AI-assisted coding, benchmarking and quick experiments, according to the docs. VM sandboxes boot a Docker or OCI image as the root filesystem of a hardware-isolated microVM and "were built with agentic RL in mind", with fast startup for thousands of concurrent sandboxes.
A checkpoint saves a sandbox's filesystem so you can start new sandboxes from it later, or fork a running one to branch your work. The docs are explicit about the boundary: "Checkpoints capture files only, not running processes or memory." That is a meaningful difference from a full VM snapshot. If your environment depends on a running database, a warmed-up interpreter or a loaded model in RAM, the fork will have the files but you must restart the processes.
A checkpoint is usable once it reaches the DURABLE state, and from then on it outlives its source sandbox. Until then the source must stay alive: deleting it early, or letting it hit its timeout, loses the checkpoint.
How to use it from the CLI
Using the prime CLI from Prime Intellect's open-source repository, the quickest path is fork, which checkpoints, waits for the save, and starts a new sandbox from it:
prime sandbox fork sbx_123 --name experiment-branch --yes
The fork inherits the source's CPU, memory and timeout unless you override them with --cpu-cores, --memory-gb or --timeout-minutes, and --wait-timeout caps how long it waits for the checkpoint.
To keep a checkpoint and restore it later, the docs give three steps:
prime sandbox checkpoint create sbx_123
prime sandbox checkpoint list sbx_123 --checkpoint-id <id>
prime sandbox checkpoint restore <id> --name restored-workspace --yes
Poll the list until the state is DURABLE, then restore. Restore accepts the same resource flags plus --team-id.
How to use it from the Python SDK
The prime_sandboxes package exposes the same flow. The documented async pattern is:
checkpoint = await sandboxes.checkpoint(sandbox_id)
await sandboxes.wait_for_checkpoint(checkpoint.id, timeout_seconds=300)
restored = await sandboxes.create(
    CreateSandboxRequest(name="restored-workspace", checkpoint_id=checkpoint.id)
)
await sandboxes.wait_for_creation(restored.id)
When restoring, omit docker_image and disk_size_gb; both come from the checkpoint. wait_for_checkpoint raises RuntimeError on failure and TimeoutError if the wait runs out, and a timeout does not mean failure, so check with get_checkpoint before deleting the source. Use list_checkpoints(sandbox_id) to inspect them. Every method has a synchronous twin on SandboxClient.
Why branching matters for agents and RL
Agent trajectories are long and expensive. A coding agent might spend minutes cloning a repo, installing dependencies and reading files before it reaches the interesting decision. With checkpoints you can pay for that setup once, then fork many sandboxes from the same state and let each try a different action. This is the pattern behind tree-search style rollouts, best-of-N at a decision point, and debugging a failed run by re-running only its last few steps.
The X post describes layering: fork from an intermediate state, checkpoint inside the branch, and fork again. The docs do not describe a limit on depth, so treat that as a workflow the primitives allow, not a guaranteed feature. The platform limits that do apply are per-account: 1,024 active sandboxes, 4,096 vCPUs and 32,768 GiB of total storage by default, with creation limits of 102,400 per hour.
Prime's platform has been moving quickly around this use case. We covered the Prime Inference launch, the acquisition of Moondream, and how DeepSeek's DSEC sandbox ran 380,000 concurrent sandboxes on Prime. Checkpointing fits that story: cheaper exploration at scale.
 A bookmark between two sections of a folded ribbon, showing a saved sandbox checkpoint that can be resumed
What people are asking
Is this the same as a VM snapshot? No. Full VM snapshots (as offered by some other sandbox vendors) capture memory and process state so a fork resumes mid-execution. Prime's checkpoint captures files only. That makes checkpoints smaller and cheaper to store, and it avoids restoring stale network connections, but it means you must re-launch servers and re-load anything held in memory.
Do forks share a disk with the original? The docs describe a fork as a copy: the new sandbox starts with the same files as the source and then diverges. Changes in the fork do not appear in the source and vice versa. Treat each fork as an independent sandbox for billing and limits, since each counts toward your active sandbox total.
Can I use this without writing RL code? Yes. A developer running a coding agent can checkpoint after the environment is set up, then fork a sandbox to try a risky refactor and throw it away if it fails. That is the same idea as a git branch, but for the whole filesystem including untracked build output.
What happens to GPU workloads? The docs say GPU sandboxes are VM-only and still listed as coming soon, requiring an explicit grant, so checkpointing GPU state is not part of what has been documented.
Where does this sit in the Prime stack? Sandboxes sit alongside Hosted Training, Environments Hub, Traces and Prime Inference in the company's docs index, so checkpoints are most useful when your rollouts are generated inside Prime environments and scored by verifiers you define.
A worked example: branch a repair task
Suppose you run a coding agent on a repo that takes six minutes to clone and install. The workflow with checkpoints looks like this.
- Create a VM sandbox from a Python image, clone the repo and install dependencies.
- Run
prime sandbox checkpoint createonce the environment is ready and wait forDURABLE. - Restore the checkpoint into several sandboxes, each given a different prompt or model.
- Score each result with your test suite and keep the best branch; delete the rest.
- Delete the base checkpoint when finished to stop storage billing.
The six-minute setup is paid once rather than for every attempt. The same shape works for evaluation harnesses, where you want many models to start from an identical filesystem.
What it costs in practice
Storage is the cost to watch. At $0.10 per GiB per month, billed hourly, a 5 GiB checkpoint costs about $0.50 a month, or roughly 0.07 cents an hour, plus an upload charge equal to one day of storage when it turns DURABLE. A 100 GiB checkpoint is about $10 a month. The running sandbox itself is billed separately: the docs give 1 vCPU, 2 GiB RAM and 5 GiB disk as about $0.046 per hour, with those launch rates valid through December 22, 2026, after which prices may change.
The practical advice: keep checkpoints small by excluding build caches, delete checkpoints you no longer branch from, and prefer one shared base checkpoint over many near-duplicates.
What is claimed and what is confirmed
- Confirmed in the docs: filesystem checkpoint, restore and fork exist for VM sandboxes, with the CLI and SDK commands above, the
DURABLEstate, the files-only limit and the pricing. - From the X post only: the "checkpoint inside a branch and fork again" framing. It is consistent with the primitives but is not spelled out as a feature in the docs we read.
- Not stated: how long a fork takes, how large checkpoints can be beyond the disk limit of 128 GiB per sandbox, and any retention limit. We did not run it ourselves, so latency claims are untested.
Which sandbox approach for which job
| Need | Reasonable choice | Why |
|---|---|---|
| Branch many rollouts from a setup state | Prime fork or checkpoint restore | Files-only snapshot, cheap storage |
| Preserve live processes or memory | A runtime with memory snapshots | Prime checkpoints do not save them |
| Isolate agent code from your host | Any microVM sandbox | See our guide to agent sandbox isolation |
| Local, throwaway runs | Git worktrees plus containers | No hosted cost |
Security note
Forking copies the filesystem, which can include secrets that were written to disk. Prime says secrets passed as encrypted sandbox secrets are injected as environment variables and never appear in logs or API responses, but a file you write them to is part of the checkpoint. Restrict network egress with the allow and deny lists, and review what a checkpoint contains before sharing it with teammates. For policy enforcement on what agents are allowed to do inside a sandbox, AgentBeam, from the explainx.ai team, stops AI agents before they take dangerous actions. Sandbox escapes are also real: see the Vercel KVM zero-day coverage.
Pricing and features are as documented on October 15, 2026; launch rates are listed as valid through December 22, 2026.