



datasette-arrows 0.1a0 shipped on November 18, 2026 as a reference plugin for Datasette's new streaming export hook. It adds Apache Arrow IPC (.arrows) downloads from tables, views, and SQL queries without loading an entire SQLite file into RAM. Sources: Simon Willison's release note, PyPI, and the datasette/datasette-arrows README.
Willison wrote that he "never releases a new plugin feature without a plugin that uses it." Here, Claude Fable 5.2 suggested Arrow streaming and implemented most of the package in one shot—a useful data point next to Datasette 1.0a43's streaming CSV work we covered earlier in November.
TL;DR
| Piece | Detail |
|---|---|
| Version | 0.1a0 on PyPI, 2026-11-18 |
| Install | datasette install datasette-arrows |
| URLs | /db/table.arrows, /db/-/query.arrows?sql=... |
| Stream all rows | ?_stream=1 or Export dialog checkbox |
| MIME | application/vnd.apache.arrow.stream |
| Python deps | datasette>=1.0a43, pyarrow |
| License | Apache-2.0 |
Why Arrow after CSV and TSV streaming
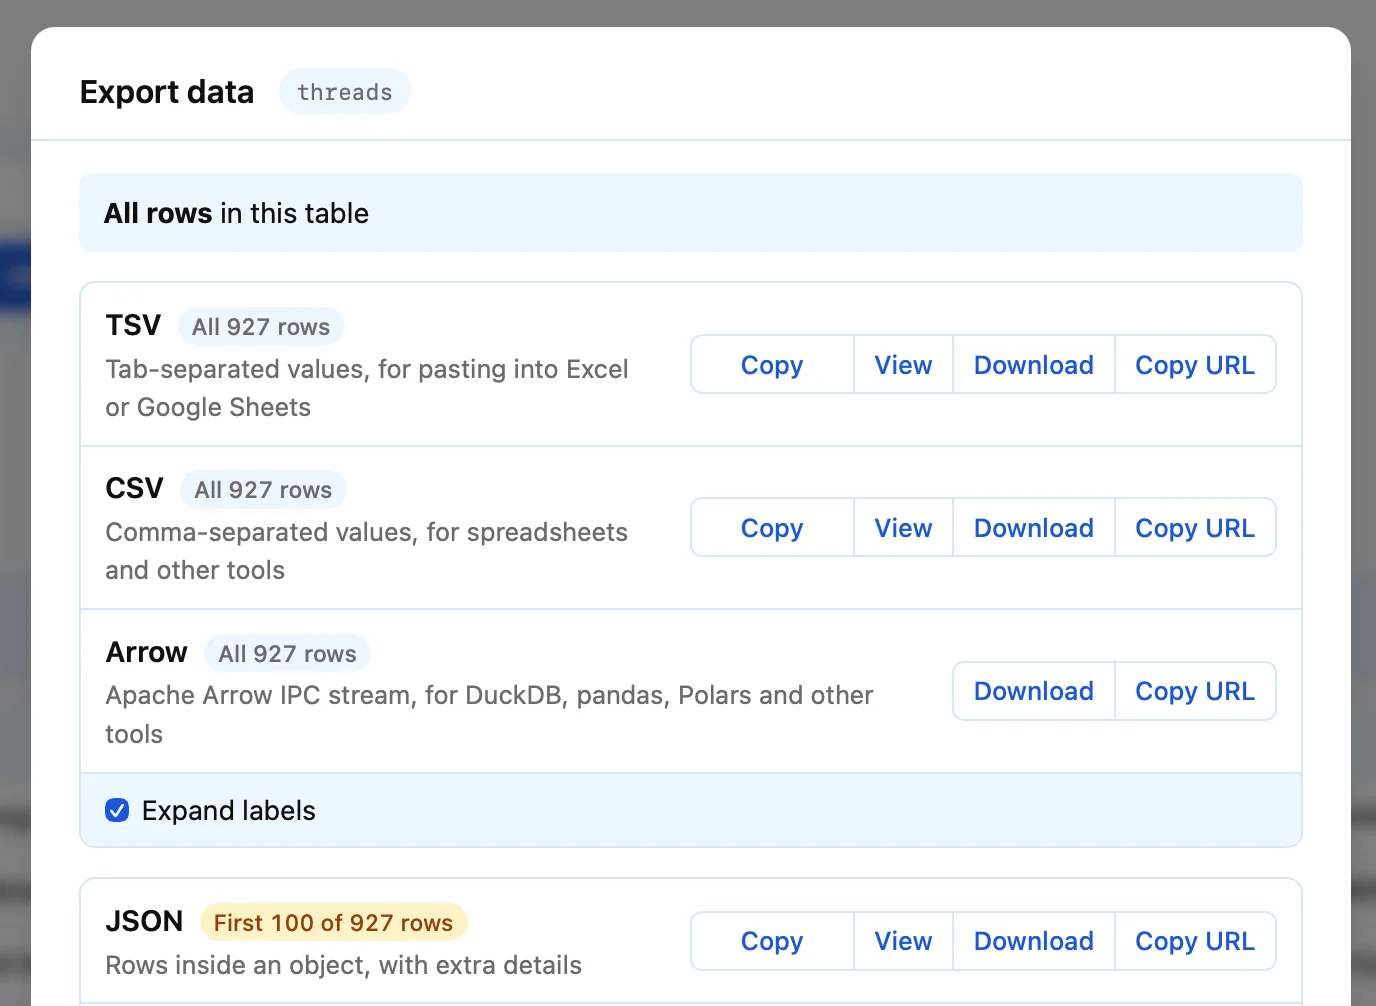 Datasette export dialog showing the new Apache Arrow streaming option
Image: Simon Willison
Datasette already streamed CSV and TSV because those formats chunk cleanly. Arrow IPC adds typed columns and zero-copy paths into pandas, Polars, and PyArrow workflows—closer to what LanceDB multimodal pipelines want than string parsing.
For publishers exposing public-interest SQLite—government logs, leaks, research drops—Arrow means a data journalist can read_all() in Python while a million-row table still streams from the server.
URL patterns and streaming semantics
 Adapter pipes meeting through a junction evoking typed columnar export streams beside CSV
From the README:
- Paginated default:
/database/table.arrowsreturns one page like HTML. - Full stream:
/database/table.arrows?_stream=1emits one record batch per page until complete. - SQL queries:
/database/-/query.arrows?sql=select+*+from+table - Download header:
?_dl=1forces file download. - Governance:
allow_streamandmax_stream_mbDatasette settings apply—same guardrails as CSV streaming.
Filters, sort orders, and ?_col= projections apply to exports, so Arrow is not a bypass around Datasette's SQL safety.
Column typing rules that bite in production
 SQL query funnel into a typed table, evoking SQLite columns mapped to Arrow types
SQLite allows mixed types; Arrow requires one type per column. The plugin infers from declared schema plus first page values:
| SQLite values seen | Arrow type |
|---|---|
| Integers | int64 |
| Floats or int/float mix | float64 |
| Text or text/number mix | string |
| Blobs or mixed with blobs | binary |
| All null, no declared type | string |
If a later page introduces an incompatible value—text in an INTEGER column—the export drops the connection so clients never treat a truncated stream as complete. Fix with explicit SQL casts, e.g. select cast(value as text) as value from ....
That behavior is stricter than CSV, which happily emits mangled strings. For ML exporters, strictness prevents silent label corruption.
Reading streams in Python
The README documents the minimal consumer:
import urllib.request
import pyarrow as pa

with urllib.request.urlopen(
    "http://localhost:8001/data/dogs.arrows?_stream=1"
) as response:
    table = pa.ipc.open_stream(response).read_all()
From there, zero-copy handoff to Polars, ** DuckDB**, or training pipelines is standard. Compare to Willison's Pyodide Datasette experiment themes: SQLite in the browser for demos, Arrow on the wire for analytics scale.
UI and release cadence caveats
Willison's screenshot uses Datasette main, where streaming formats will soon sit beside CSV/TSV under "All rows in this table" in the export dialog. 0.1a0 shipped before that UI grouping landed in a numbered alpha, so early adopters may need main or the next alpha for the polished dialog.
The plugin requires streaming output renderers—present on main, not necessarily on the latest tagged release you run in production. Pin versions explicitly in Docker images.
How this fits explainx.ai's tool coverage
datasette-arrows is small but exemplary: it shows how plugin hooks should ship with reference implementations. The same week brought Vercel Board for agent coordination and CodeRabbit Verify for runtime QA—different layers, same lesson: agents need contracts, not just models.
For local AI, Arrow exports pair with AirLLM-style constrained inference when you are featurizing public tables on modest GPUs—download features, not giant CSV text.
Security and publishing notes
Streaming exports can exfiltrate large tables if allow_stream is on for sensitive databases. Treat .arrows endpoints like CSV download permissions. Row-level auth plugins still apply; Arrow does not magically redact columns.
If you expose Datasette on the public internet, keep stored-query advisory fixes patched—streaming does not fix SQL injection in saved queries.
Try it in fifteen minutes
- Install Datasette main or >=1.0a43 with streaming renderers enabled.
datasette install datasette-arrowsdatasette serve data.db- Open a table, confirm Arrow in Export data.
curl -o out.arrows 'http://localhost:8001/db/table.arrows?_stream=1'- Load with pyarrow and compare row count to
select count(*).
Open an issue on datasette/datasette-arrows if type coercion fails on real-world messy columns—that feedback shapes 1.0.
Hook mechanics: register_output_renderer()
Datasette 1.0a43 extended plugins so authors can register streaming output renderers alongside built-in CSV and TSV. The core idea: fetch a page of rows, serialize a chunk, repeat—never materialize the whole table in the Datasette process. datasette-arrows is the reference implementation for binary columnar output instead of delimited text.
Plugin authors should copy its patterns:
- Honor
?_stream=1and dialog Include all rows. - Respect
allow_streamandmax_stream_mbcaps. - Fail hard on type conflicts rather than emit silent corruption.
If you maintain custom SQLite packs for newsrooms or NGOs, shipping Arrow lowers the bar for partner universities that already standardize on PyArrow.
Integration sketches beyond pyarrow
Polars can read Arrow streams with pl.read_ipc_stream. DuckDB can attach Arrow streams for SQL transforms before Parquet archival. Training stacks that expect HF datasets can still ingest Arrow, convert once to sharded Parquet, and push to LanceDB if you later need vector search.
For agents, a coding agent that knows Arrow schemas can validate column dtypes before fine-tune—fewer silent NaN bugs than CSV guesswork.
Comparison to CSV for million-row tables
CSV wins on universal tool support and human grep. Arrow wins when:
- Columns are numeric-heavy (counts, lat/lon, embeddings serialized as lists).
- You need stable dtypes across pages.
- You pipeline into Python ML without parse overhead.
Benchmark on your table: time table.csv?_stream=1 versus table.arrows?_stream=1 into Polars on the same laptop. Arrow should dominate when columns > 20 or rows > 1M.
Maintainer and CI notes
The GitHub repo ships uv run pytest. Depend on datasette>=1.0a43 and pyarrow. Because streaming renderers lagged tagged releases when 0.1a0 shipped, pin Docker images to datasette:main only if you accept moving targets—otherwise wait for the next alpha Willison promised for export dialog grouping.
Watch Datasette plugins directory for composition: combine datasette-arrows with label plugins for foreign keys in Arrow exports via ?_labels=on.
When this release is not news for you
If you do not run Datasette, skip this plugin. If you only publish 500-row tables, CSV is fine. If you are on Datasette versions before 1.0a43, upgrade stored-query patches before experimenting.
Observability and abuse monitoring
Operators should log .arrows?_stream=1 hits the same way they log large CSV exports. A sudden spike may mean scraping, not legitimate research. Combine max_stream_mb with rate limits at the reverse proxy when tables contain PII.
For multitenant Datasette Cloud (if you run one), partition plugins per deployment so Arrow cannot become a covert exfil channel from restricted databases.
Roadmap signals from Willison's release cadence
Willison's post notes the export dialog UI will group streaming formats in the next alpha after 0.1a0. That means early adopters may field support tickets from users who do not see Include all rows beside Arrow yet. Document ?_stream=1 deep links in your data handbook until the UI catches up.
Future plugins may add Parquet stream, GeoArrow, or embedding-specific layouts using the same hook—datasette-arrows is the template, not the final catalog.
Ethics of publishing queryable public data
Arrow makes re-identification attacks faster when tables include quasi-identifiers. If you publish census microdata or leaked corp tables, review k-anonymity basics even when the format is modern. Streaming does not remove duty of care.
Journalists pairing Datasette with AI Overviews traffic loss stories should remember: machines read Arrow faster than humans read HTML, changing scraper economics overnight.
Troubleshooting common failures
Empty stream after 200 OK: Check whether you forgot ?_stream=1 on a multi-million-row table; the first response may be only one page.
Connection reset mid-download: Often type coercion failure on a later page. Re-run export with a SQL query that casts messy columns to text.
Plugin not listed: Confirm uv run datasette plugins shows datasette-arrows and that you are on a Datasette build with streaming renderers enabled.
pyarrow ImportError: Install pyarrow in the client environment reading the stream, not only on the server.
Foreign keys missing labels: Enable ?_labels=on on the URL or verify the labels plugin chain you expect is active.
Why Willison shipped Arrow before Parquet stream
Arrow IPC is row-batch oriented for incremental HTTP, matching Datasette's page loop. Parquet wants column stripes and is heavier to stream without custom footers. If Parquet streaming arrives later, expect different memory tradeoffs—Arrow remains the low-latency wire format for Python analytics.
Ecosystem placement next to Lance and DuckDB
Teams exporting SQLite snapshots to Lance for vector search can treat datasette-arrows as step one (fast extract) before offline convert. Teams on DuckDB can ATTACH Arrow streams for JOIN against CSV dimensions without double disk use.
None of that is automatic—you still write glue—but you avoid CSV parse tax on wide tables.