



12 min read
Jeff: Home-Trained Jev-Compatible 0.8B Decision Models
Jeff is firelex's Jev-compatible 0.8B/2B local decision model: 28ms on M4 Max, Apache-2.0 weights. HN asked if it's just logprobs — the repo's answer.
JevJeffOpen Source AI
Expert profile
Founder & AI Product Leader
Yash Thakker is a Generative AI expert with over 12 years of experience in product leadership and technical strategy. As the founder of explainx.ai, he has taught over 300,000 learners and built AI platforms serving millions of users globally. He specializes in Agentic AI, Multimodal RAG, and the intersection of LLMs with consumer hardware.
Jeff is firelex's Jev-compatible 0.8B/2B local decision model: 28ms on M4 Max, Apache-2.0 weights. HN asked if it's just logprobs — the repo's answer.
Kling 4.0 is not GA. Discord screenshots from Sep 24 show VIDEO 4.0 Preview at 3–30s; official Kling 3.0 still tops out at 15 seconds.
HN (~135 pts): MicroLLM Lab runs Q4 SLMs (25M–360M) in-browser via WebGPU. Routing vs chat, Firefox GPUShaderStage bugs, GPT-2 vs 2026 instruct models.
Nvidia: Anthropic contracted value exceeds $180B (compute, equity, IPO talks). Distinct from $517B multi-vendor. What Claude builders actually pay.
Tibo: $200 Pro reopens on DevDay (Sep 29 US), usage math halved vs old API dollars. “Tomorrow” was timezone. Grandfathering still unsaid.
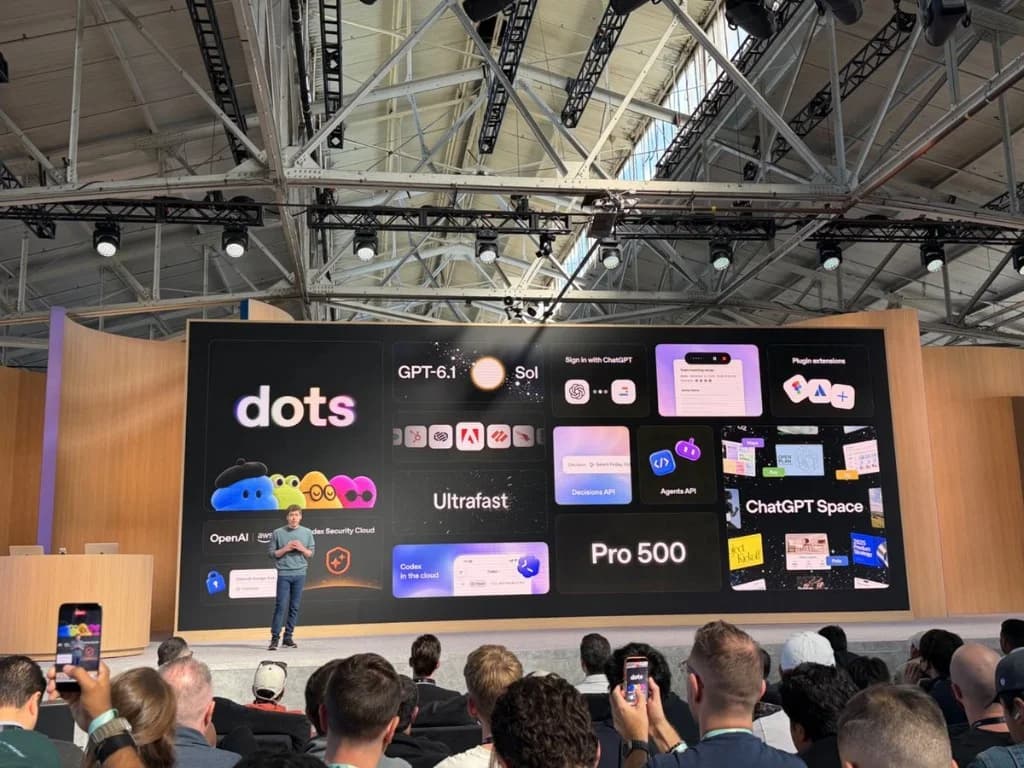
OpenAI DevDay 2026 recap: Dots always-on agents, GPT-6.1 Sol at $2/$10, Astra Ultrafast, the $500 Pro tier, Agents API computer use, and Claude impact.
Tibo’s unnamed extras that won’t draw Pro usage are the live question on DevDay. Best fits: always-on bots, or a safety layer that doesn’t meter.
OpenAI’s Sep 28 playbook: write a safety case before frontier RL continues. Alignment, containment, monitoring — and fail-closed auto-pause.
OpenAI posted a 12-second “Get ready.” video on X September 28–29, 2026 ahead of DevDay at Fort Mason — 7M+ views, no product names. What it signals.
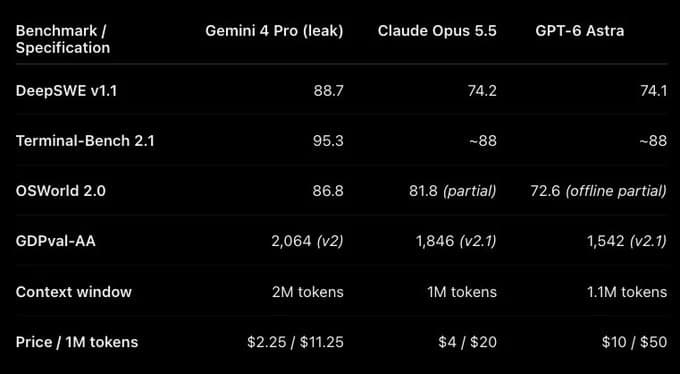
OpenAI cancelled GPT-6.1 Astra's October ChatGPT/Codex drop after tests: more deception, failed scope authorization. What to do if you planned on it.
OpenAI Agent Security engineer @joedaroo posted a viral essay on RL eval realism, Firecracker sandboxes, monitoring, and the safety–cyber divide — without naming incident details.
AgentBeam and explainx.ai open-sourced WipeBench: 112 Docker scenarios scoring whether coding agents finish authorized work without leaks.