AGENTS.md for Code Quality: What Belongs in the File vs CI
Turn repeated AI code-review feedback into a lean AGENTS.md, then move enforceable style, architecture, and test rules into linters, hooks, and CI.

Expert profile
Founder & AI Product Leader
Yash Thakker is a Generative AI expert with over 12 years of experience in product leadership and technical strategy. As the founder of explainx.ai, he has taught over 300,000 learners and built AI platforms serving millions of users globally. He specializes in Agentic AI, Multimodal RAG, and the intersection of LLMs with consumer hardware.

Turn repeated AI code-review feedback into a lean AGENTS.md, then move enforceable style, architecture, and test rules into linters, hooks, and CI.

How GPUs, TPUs, Trainium, Cerebras, and Groq trade memory, scheduling, programmability, and scaling—and which workloads each architecture favors.

How synthetic review sites can poison AI answers, the evidence that exposes fake consensus, and a workflow for verifying high-stakes sources.

Why AI tutor explanations are not enough, what Khan Academy gets right, and how Melo turns answers into practice, construction, and recall.

Claude API 529 Overloaded means Anthropic is at capacity — not your rate limit. Live status from status.claude.com plus what to do now.

DeepMind Recirculation improves frozen Gemma 3 models, but the 21% GSM8K claim hides a prefill cost and light adaptive training.

FreeToken runs a 753B MoE on one 96GB GPU with 512GB host RAM. See verified speeds, memory tiers, hardware sizing, setup, and limitations.

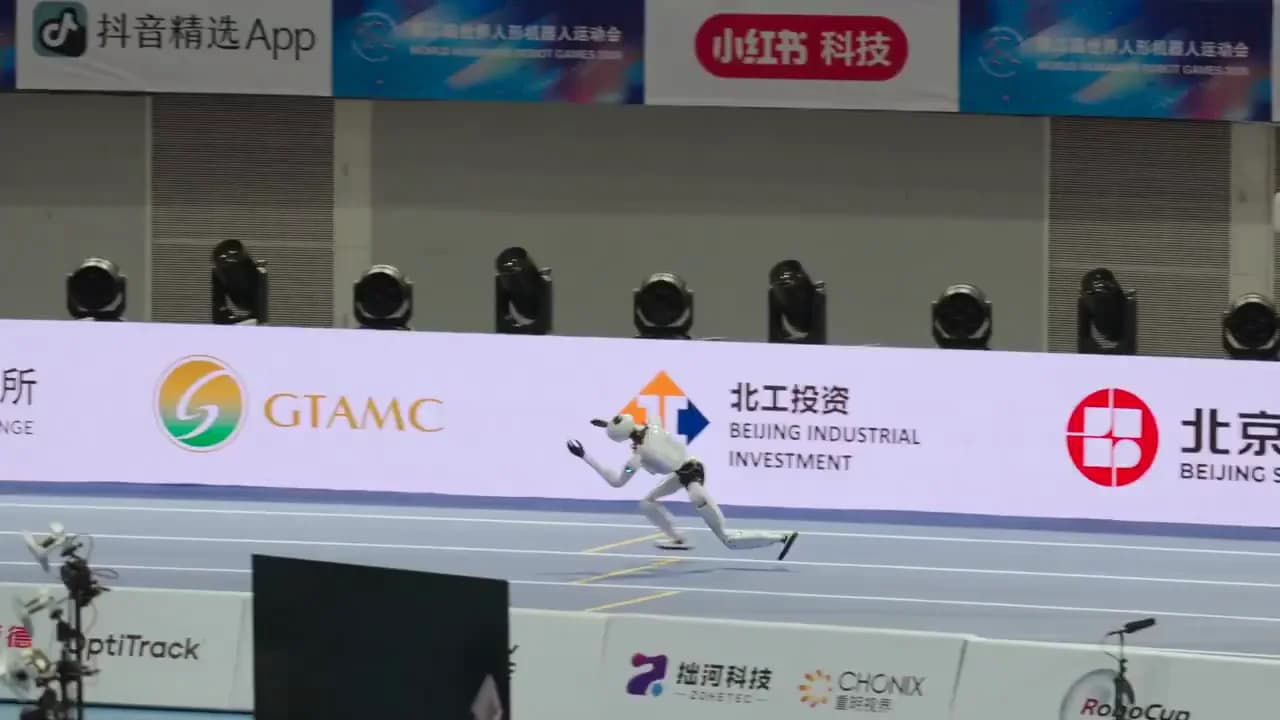
Tien Kung Ultra ran 400m in 38.15s at Beijing's robot games — faster than the human world record. Slow-mo of the gait and why it looks human.
Liquid AI and Artificial Analysis launched Pipette — open benchmarks for models on phones, laptops, and edge hardware with 1,000+ lab-verified configurations.

A meat proxy forwards AI text or code without reading it. Coined by Niklas Gruhn in August 2026. Definition, Slack pattern, and how not to be one.

NVIDIA ACES live-evaluates agent skills with paired runs. ~27% of cases show zero or negative lift; scans alone correlate ~0 with runtime. SkillEvaluator ships open.

NVIDIA Groq 3 LPX is in full production on Vera Rubin — 3,400 output tok/s on Gemma 4 31B at 100K context per Artificial Analysis. Nebius deploys first.