



llama.cpp just fixed one of the quiet reasons speculative decoding disappoints on a Mac. Build b11404, published October 5, 2026, adds Metal "few-row" matrix kernels, and a follow-up merged on October 7 extends them to almost every quantization format. On an M3 Ultra, the author's own kernel benchmarks show the new paths running up to 4.4x faster on the small batches that speculative decoding creates.
A headline circulating this week puts it as "3.4x faster speculative decoding on M3 Ultra." That is not a number we could find in the primary sources, and it is easy to misread. The PRs report matmul kernel speedups, not end-to-end tokens per second. This post explains what changed, what the numbers say, what they do not say, and how to measure the benefit on your own hardware. It sits next to our earlier local-inference coverage, including the Gemma 4 MLX Mac speedup and the Perplexity Lily Apple Silicon engine.
TL;DR: what changed and what to expect
| Question | Answer |
|---|---|
| What shipped? | Metal few-row MMA mat-mul kernels for 2 to 16 rows (PR 29869, in build b11404), extended to the remaining types by PR 30065 (merged October 7). |
| Who benefits? | Mac users on Apple7 and newer GPUs without the tensor API running speculative decoding, or other small-batch decoding. |
| Do I need a flag? | No. Dispatch is automatic once the row count passes a per-type threshold. |
| Best published number? | 4.41x on Q1_0 at 8 rows, 4.30x on Q2_K at 8 rows, 4.03x on TQ2_0 at 16 rows (M3 Ultra, matmul kernel only). |
| Does plain chat get faster? | Not much. One-row generation is a matrix-vector job and the PR says 512-row results are within 1 percent of before. |
| Is the 3.4x end-to-end figure confirmed? | No. It is not in the PRs or release notes. Treat it as unverified. |
| Is the build stable? | b11404 is marked a pre-release on GitHub. Like all llama.cpp builds it moves daily. |
Why was speculative decoding slow on Metal in the first place?
Speculative decoding is a trick for generating text faster without changing the output. A small, quick "draft" proposes several next tokens. The big model then checks all of them in a single forward pass and keeps the ones it agrees with. The idea comes from the 2022 paper on fast inference from transformers via speculative decoding, and it is now standard in local runtimes. We covered a production version in our DeepSeek DSpark guide.
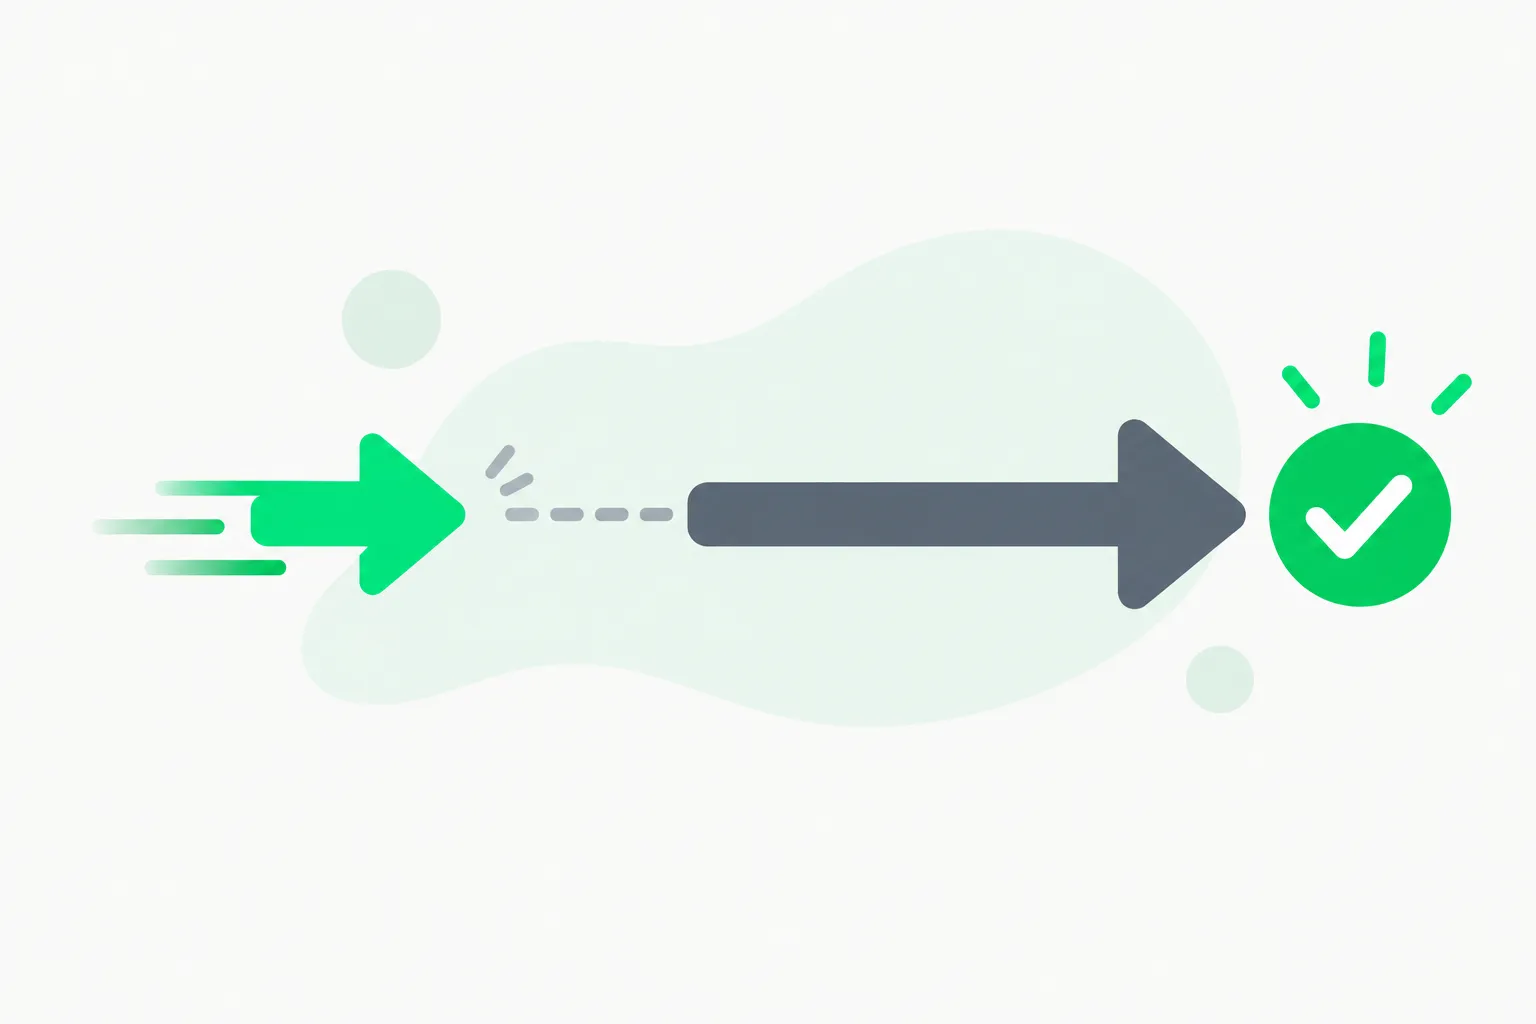 A small fast arrow running ahead of a longer checking arrow with a tick, showing the draft-then-verify loop in speculative decoding
The catch is the shape of the verification math. Normal generation multiplies the model weights by one vector (one row). Verification multiplies them by a small matrix of two to sixteen rows, one per drafted token. On a GPU, that is the awkward middle: too many rows for a pure matrix-vector kernel to stay efficient, too few for a big-batch matrix kernel to pay off.
According to the b11404 release notes, Metal handled these cases with matrix-vector kernels whose cost grows with every extra row. The notes state that on an M3 Ultra, DFlash2 decoding was slower than serial decoding. In other words, the verification step ate the gains the draft was supposed to provide.
What the new kernels do
The release notes for PR 29869 describe the fix in three parts.
- New kernels for 2 to 16 rows. They use 8x8 simdgroup matrices. Each weight is dequantized once and reused for all rows, and simdgroups in a threadgroup split the K dimension to keep the GPU busy.
- Per-type thresholds. The kernels only kick in where they beat the old path on an M3 Ultra: at 6 rows for F32, 3 rows for F16, Q4_K, Q5_0 and Q5_1, and 2 rows for the other types. Q4_0, Q8_0 and Q5_K get dedicated kernels, while F32, F16, Q4_1, Q5_0, Q5_1, Q4_K and Q6_K use a generic path.
- Fusion. A matmul followed by an add can fold a same-shape residual into the matrix store, and long CONCAT rows are split across threadgroups when there are few rows.
They apply only on Apple7 and newer GPUs without the tensor API, so the benefit is tied to GPU family rather than to the M3 Ultra alone, although that machine is where the author tuned the thresholds.
 Laptop outline with a small green chip representing Apple Silicon running local model inference
PR 30065: the remaining quantization types
The first PR covered the common formats. PR 30065, "metal : few-row MMA mat-mul for the remaining src0 types," by pratiknarola-t, was opened October 6, approved October 7 and merged the same day by Georgi Gerganov. It extends the kernel to every type that has a 16-weight dequantizer: BF16, Q1_0, Q2_0, MXFP4, Q2_K, Q3_K, TQ2_0 and the IQ family (IQ1_S, IQ1_M, IQ2_XXS, IQ2_XS, IQ2_S, IQ3_XXS, IQ3_S, IQ4_NL, IQ4_XS).
The author's M3 Ultra measurements, for a 4096 by 14336 matmul using test-backend-ops perf -o MUL_MAT, relative to the prior master:
| Type | 2 rows | 4 rows | 8 rows | 16 rows |
|---|---|---|---|---|
| BF16 | n/a | 1.34x | 2.83x | 3.63x |
| Q1_0 | 1.27x | 2.33x | 4.41x | 3.38x |
| Q2_K | n/a | 2.13x | 4.30x | 3.64x |
| TQ2_0 | n/a | n/a | 1.71x | 4.03x |
| IQ2_XS | 1.07x | 1.91x | 3.48x | 3.67x |
Across the 9 to 16 row range the PR reports 3.06x to 4.14x for the newly covered types. Types that already had these kernels stayed within about 3 percent of master, and everything was within 1 percent at 512 rows, so large-batch prompt processing is unaffected. The author notes some run-to-run variance on the machine and reports test-backend-ops passing 3,314 of 3,314 MUL_MAT and MUL_MAT_ID cases on the M3 Ultra, plus the new cases passing on CUDA and Vulkan hardware. One cost: the mul_mv_mma library takes longer to compile, from 0.33 s to 0.67 s on an M5.
Does this make speculative decoding 3.4x faster?
No, and this is the part to keep straight. Three layers separate a kernel speedup from the tokens per second you see.
- Kernel versus model. A matmul is only part of a decode step. Attention, sampling, the draft model's own passes and memory traffic are not sped up by this change.
- Acceptance rate. Speculative decoding only wins if the big model accepts enough drafted tokens. A poor draft pair can lose even with a perfect kernel.
- Quantization. The biggest ratios in the table are on aggressive formats such as Q1_0, Q2_K and TQ2_0. If you run Q4_K_M or Q8_0, the gain is the smaller, dedicated-kernel kind.
Independent measurements already showed how uneven Metal results can be. A recent academic study, "Lossless but Not Free: An Empirical Anatomy of Speculative Decoding on Consumer Hardware", reports a best-case 1.61x wall-clock speedup with three of five configurations slowing down, and attributes part of that to the quantized Metal backend running "parallel" verification serially. That is exactly the behavior these kernels target, so retesting after b11404 is worthwhile. A separate GitHub issue against an older build, b9330, reported multi-token-prediction drafting being up to 28 percent slower than baseline on Metal. That predates the new kernels, so it is a good candidate to rerun rather than a current verdict.
How to test it on your Mac
Pull a build at or after b11404 and compare with and without drafting on the same prompt.
brew install llama.cpp   # or build from source at tag b11404 or later
llama-server -m big-model-Q4_K_M.gguf \
  -md small-draft-Q8_0.gguf \
  --draft-max 8 --draft-min 2 -ngl 99
Flag names change often in llama.cpp, so confirm with llama-server --help on your build. Then measure:
- Run the same 500-token generation with the draft model disabled and enabled.
- Record generation tokens per second and the draft acceptance rate the server logs.
- Try draft lengths of 4, 8 and 16, since the new kernels cover 2 to 16 rows and the best value depends on acceptance.
- If you maintain a regression suite, run
test-backend-opsfor MUL_MAT to confirm correctness on your device.
If you see a slowdown, check acceptance before blaming the kernel. A draft that is wrong half the time can cost more than it saves.
Who should care
 A small house-shaped box with a glowing green core, representing a local LLM running on a home machine
Mac Studio and MacBook Pro owners running big local models are the clearest winners: the slower the base model, the more a successful draft saves. That includes the very large mixture-of-experts models that people now run on high-memory Macs, as in our write-ups of antirez's DwarfStar ds4 local inference engine and the local AI buying guide for the Surface Laptop Ultra.
People who run heavily quantized models (1 to 3 bit) get the largest relative boosts because those were previously the least optimized on Metal.
People who only chat with a model at one request at a time should expect little change unless they enable drafting.
Tool builders that wrap llama.cpp, such as desktop apps, should watch for bundled-version bumps, because the gain arrives automatically when they update. Our llama.cpp decision model support post shows how fast the project's feature surface moves, and the Transformers GGUF parity update covers how its file format is spreading.
Caveats
- Kernel benchmarks come from the PR author, on one machine, with acknowledged variance. We have not independently reproduced them.
- b11404 is flagged a pre-release. Pin a version in anything you ship.
- The kernels apply to Apple7+ GPUs without the tensor API. Newer chips with tensor support may take a different path.
- Compile times for the Metal library roughly doubled in the author's test.
Details above are accurate as of October 10, 2026. Check the llama.cpp releases page for current builds.